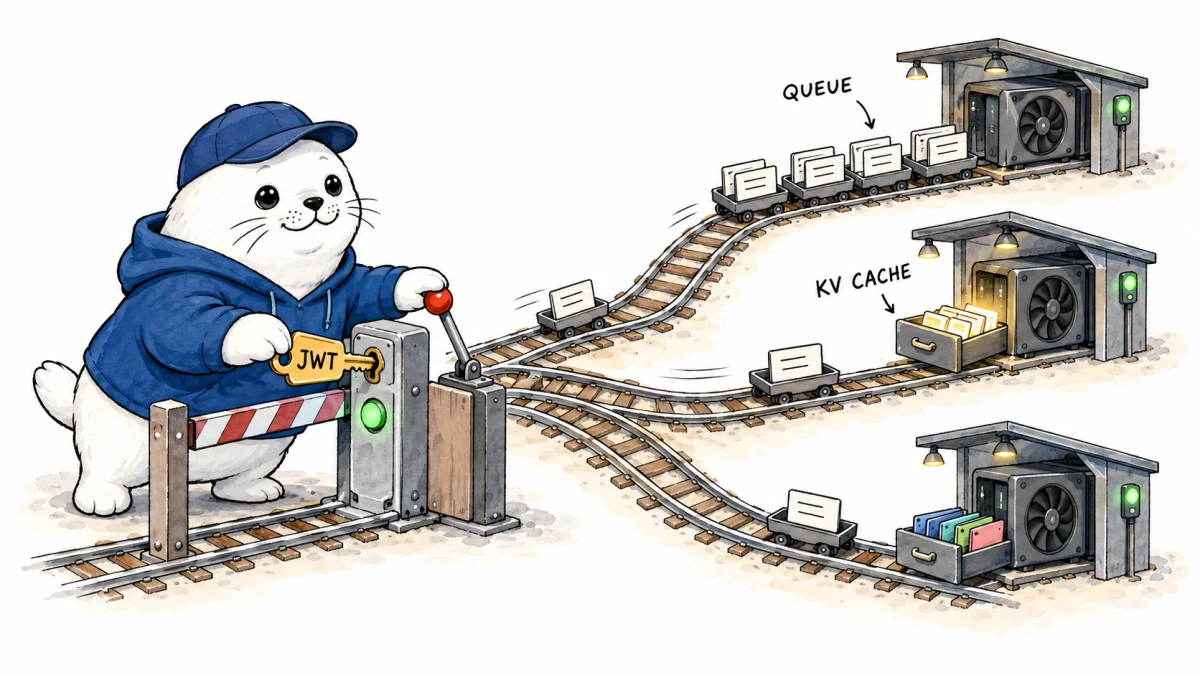
AWS HyperPod Inference Gateway Routes LLM Traffic by GPU State, but JWT Is Optional
AWS HyperPod Inference Gateway routes LLM requests with queue, cache and adapter signals. Enable JWT and verify serving-engine metrics before production.
Frontier models, comparisons, and how to choose what fits your work.
AWS HyperPod Inference Gateway routes LLM requests with queue, cache and adapter signals. Enable JWT and verify serving-engine metrics before production.
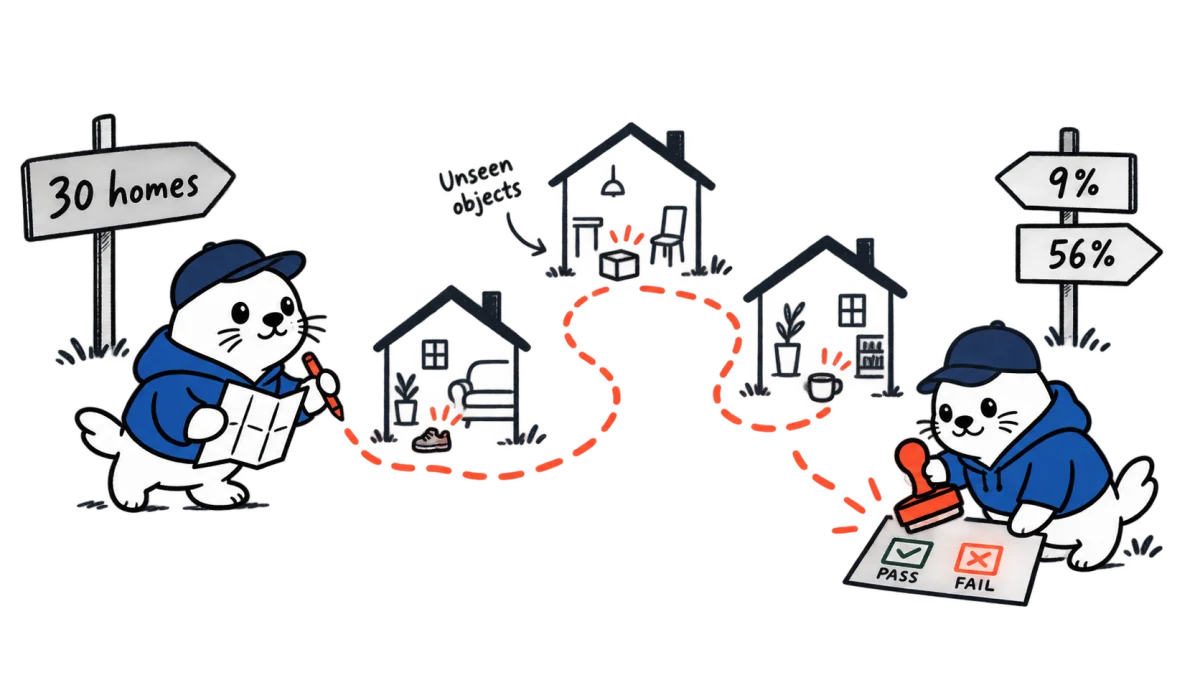
Figure Helix 2.5 reached a company-reported 56% success rate across 30 unseen homes. We audit the protocol, baseline and meaning of zero-shot.
Salesforce Koa is a CRM reasoning model built on NVIDIA Nemotron 3 Super. It is in a select pilot, with US availability expected in…
IBM researchers proved theoretical separations between shallow quantum circuits and restricted LLMs. Here is what the result does and does not show.
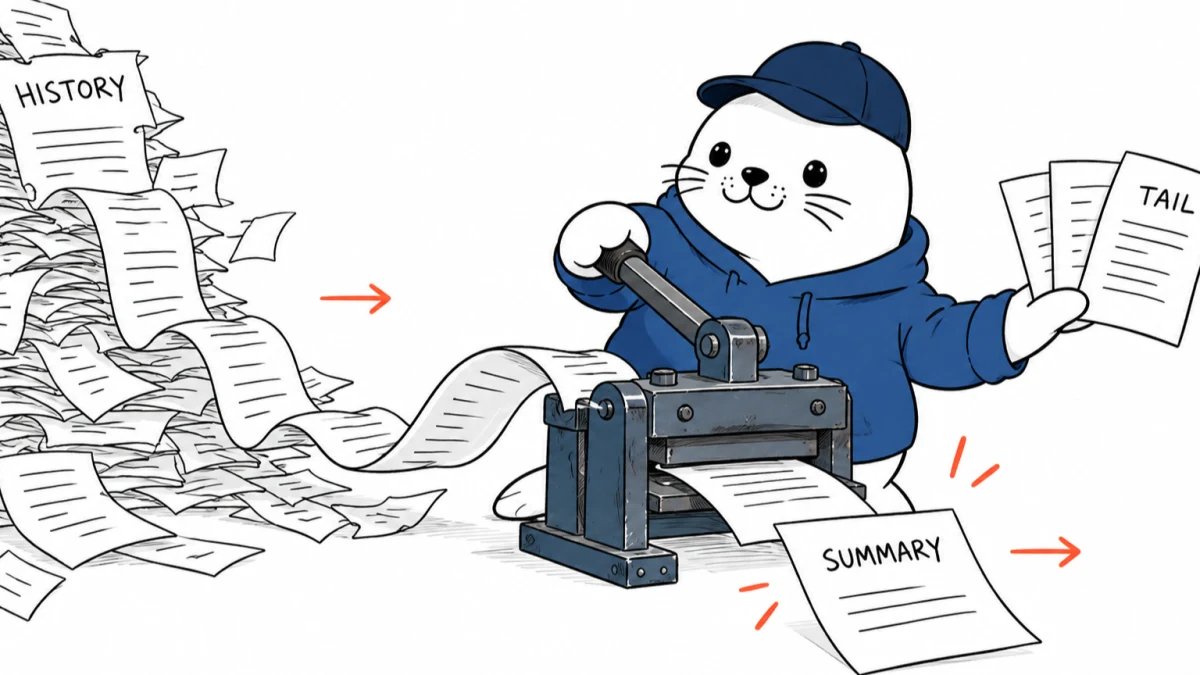
Claude API compaction replaces old message history with a signed summary block while preserving a recent tail. This guide maps the new failure modes.
Gemini 3.8 Live adds a production audio model and an extended-thinking variant. Here are the migration changes, state signals, limits and prices.
AWS published an eight-step model customization spectrum. This vendor-neutral guide maps knowledge, behavior, latency and cost failures to the right step.
NVIDIA says its JAX MoE training stack lifted DeepSeek-V3 from 103 to 1,068 TFLOPS per GPU on GB200. Here is what changed and how…
Cohere North Small Translate activates 25B of 218B parameters across 50 languages, with gated non-commercial weights and a high-end GPU floor.
IBM Granite time series adds a 385M-parameter zero-shot forecasting model with 99 quantiles, open weights and one benchmark caveat.
AWS LLM latency updates target prompt-prefix reuse and model cold starts separately. Here is how to diagnose which cache your workload needs.
AWS compares OpenAI models by cost per correct answer instead of token price. The result is useful, but model settings are not fully matched.