NVIDIA says a set of JAX and Transformer Engine optimizations increased DeepSeek-V3 training throughput on GB200 from 103 to 1,068 TFLOPS per GPU. That is a 10.4x company-reported gain on a named workload and hardware stack, not a universal speedup for every mixture-of-experts model.
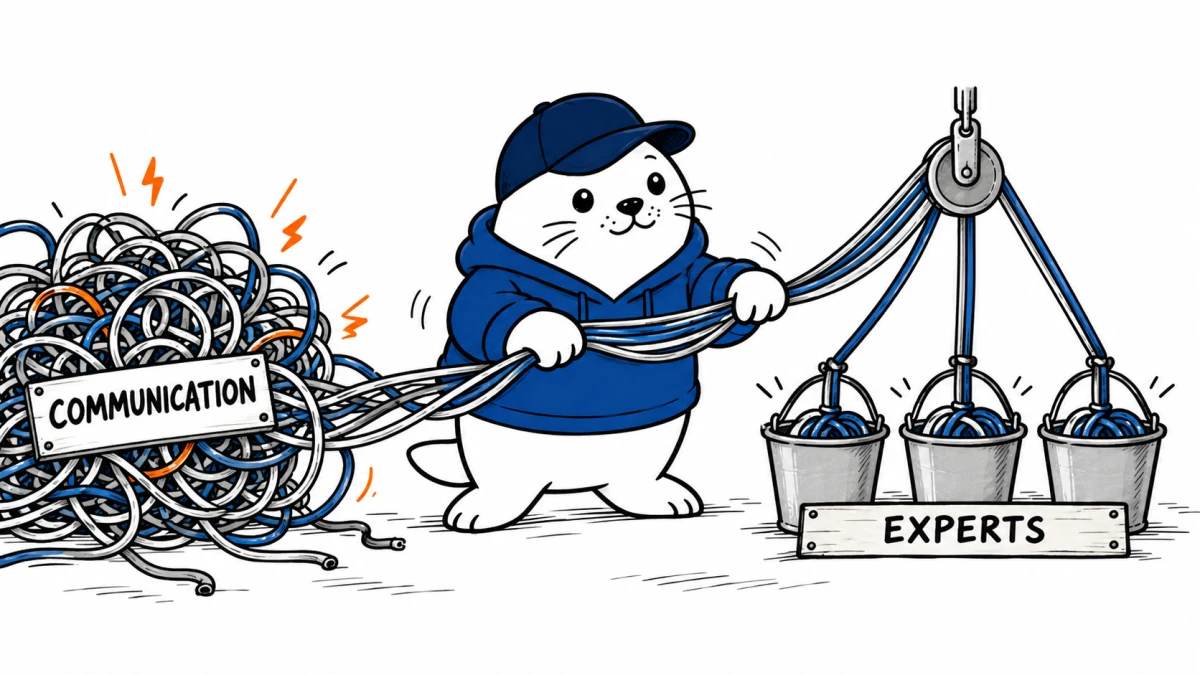
The NVIDIA technical post was published September 14, 2026. It reports that inter-GPU communication consumed 84 percent of accumulated kernel time in the unoptimized GB200 baseline. The work attacks that bottleneck across expert math, token movement, memory and overlapping collectives.
The benchmark claim in one table
| Measurement | NVIDIA-reported result | Boundary |
|---|---|---|
| Unoptimized GB200 baseline | 103 TFLOPS/GPU | DeepSeek-V3 training |
| Optimized GB200 path | 1,068 TFLOPS/GPU | JAX plus Transformer Engine stack |
| Improvement | 10.4x | Same stated workload and hardware family |
| Multirack scaling | 97% efficiency at 1,024 GPUs | DeepSeek-V3 671B on GB300 NVL72 |
The GB200 throughput comparison and GB300 scaling result are related but not the same experiment. Keep the hardware label attached to each figure.
Dropless MoE keeps every routed token
In mixture-of-experts training, a router sends each token to a small subset of expert networks. Expert loads are uneven, so the resulting matrices are ragged. Capacity-based systems simplify the shapes by padding or dropping overflow tokens. Dropless training processes every selected token, preserving the training signal but demanding kernels that can handle variable workloads efficiently.
Grouped GEMM removes padded expert work
A loop of ordinary GEMM calls can require device-to-host token counts and break CUDA graphs. A padded batch computes the largest capacity even when an expert receives fewer tokens. NVIDIA’s grouped GEMM handles multiple expert matrix operations in one kernel call using their actual token counts. On Blackwell, the path also enables MXFP8 block scaling for expert matrix multiplication.
NCCL EP targets the movement around each expert
Expert parallelism has two transport phases. Dispatch moves routed tokens to the GPU that hosts the expert. Combine returns the results and restores their original order. NVIDIA says its NCCL EP path fuses these stages and deduplicates tokens when the same token must reach multiple experts on a rank or remote node.
Grouped GEMM speeds the work inside experts. NCCL EP reduces the overhead around them. Host activation offloading and XLA multistreaming collectives then address memory pressure and overlap independent communication across NVLink and InfiniBand.
A reproduction needs correctness gates, not just throughput
- Start from the NGC MaxText container with Transformer Engine enabled.
- Record GPU model, node topology, software versions, precision and batch configuration.
- Reproduce the baseline before enabling grouped GEMM, expert parallelism or host offloading.
- Add one optimization at a time and capture tokens per second, TFLOPS per GPU and exposed communication.
- Compare loss curves, router balance, overflow behavior and numerical stability.
- Repeat after scale changes because a single-node win can disappear across racks.
Who can benefit from this work
The techniques matter most to teams training large dropless MoE systems on NVIDIA clusters with JAX and MaxText. They are less relevant to API users, inference-only deployments or small dense models. The real transfer lesson is broader: profile token movement and ragged expert math before buying more accelerators.
Our Nemotron 3 Ultra infrastructure analysis separates hardware-specific vendor claims from general deployment guidance. The AI GitHub repository guide can help teams locate the open implementation components around JAX and training systems.
The practical verdict
NVIDIA’s result is technically interesting because it names the initial bottleneck and publishes a container path. Treat 10.4x as a vendor-reported result for the stated DeepSeek-V3 setup. A credible reproduction must match system topology, verify training behavior and show which optimization contributes each part of the gain.
Primary source
Checked September 14, 2026. Throughput, communication share and scaling figures are NVIDIA-reported and have not been independently reproduced by MustHave.ai.