AWS has added an LLM-aware routing layer for SageMaker HyperPod. Its scheduling signals are sophisticated, but the production decision begins with a simpler fact: request-level authentication is not enabled by default.
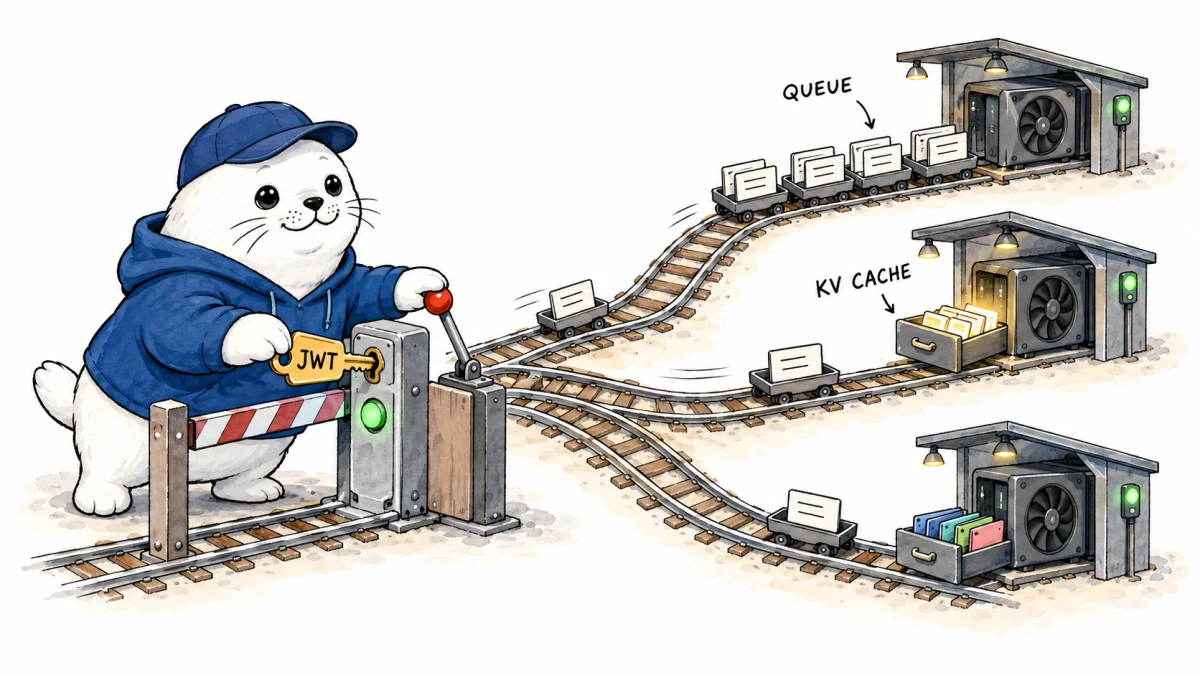
AWS HyperPod Inference Gateway is a Kubernetes-native router for large-model inference on Amazon EKS. It reads the model requested in an OpenAI-compatible payload and can score candidate pods using queue depth, running requests, predicted latency, KV-cache state, prefix affinity and LoRA-adapter affinity.
Enable the JWT gate before production traffic
AWS documentation states that the gateway does not provide request-level authentication by default. Network controls can limit who reaches the endpoint, but they do not prove which application or user sent a request. For a production deployment, configure the gateway’s spec.auth.jwt settings and test rejected, expired and incorrectly signed tokens before routing real prompts.
Keep the network boundary as well. JWT validation and VPC controls solve different problems: the first authenticates the request, while the second constrains the path to the service. Add authorization and rate limits in the surrounding application when different callers have different model or cost permissions.
What the gateway routes
| Signal | What it tells the router | Operational check |
|---|---|---|
| Queue depth | How much work is waiting at a pod. | Confirm the metric reflects the serving engine and request class. |
| Running requests | How much work is already executing. | Watch for long generations that occupy capacity. |
| Predicted latency | The estimated wait and service time. | Compare predictions with observed percentile latency. |
| KV-cache and prefix affinity | Whether a warm prompt prefix may be reusable. | Measure hit rate and first-token latency together. |
| LoRA-adapter affinity | Whether the requested adapter is already available. | Track adapter load time, eviction and memory pressure. |
The router uses the model field to choose a service, so clients must send a consistent model name. A typo or stale alias can become a routing failure rather than a model-quality problem. Pin the public model identifier separately from the internal deployment name.
Version prerequisites are part of the design
AWS lists the inference add-on as v2.0.0-eksbuild.2. Its documentation calls for vLLM 0.9.2 or later, or SGLang 0.3.5.post1 or later, for the documented metric behavior. Treat those versions as a contract. An older serving engine may still answer requests while failing to expose the signals the router expects.
Record the EKS version, add-on version, serving engine, container digest and configuration together. During an upgrade, validate metric names and units before sending traffic. A scheduler that receives empty or stale metrics can look healthy while making poor placement decisions.
How the OpenAI-compatible path helps
An OpenAI-compatible request shape makes it easier to connect clients that already speak common chat or completion conventions. Compatibility does not mean feature parity. Test streaming, error envelopes, timeouts, token accounting and model-name behavior with the exact SDK version used by the application.
Place protocol translation at one clear boundary. If an application proxy and the gateway both rewrite model names or errors, incident traces become hard to follow. Attach a request ID before the gateway and carry it through the selected pod.
Do not generalize the AWS benchmark
AWS reports performance improvements against round-robin routing under its tested workloads. Those are vendor-reported results, not a guarantee for every prompt mix, model, GPU or cache pattern. Queue-aware routing can add little when requests are uniform, and cache affinity can compete with load balancing when one prefix becomes very popular.
Build a replay from the workload you expect. Compare round robin with the gateway on time to first token, inter-token latency, end-to-end latency, throughput, errors, GPU utilization and cost per completed request. Preserve the prompt-length and output-length distributions because averages can hide a slow tail.
A production rollout checklist
- Install and pin the add-on. Record the gateway and serving-engine versions.
- Configure JWT validation. Test missing, expired, wrong-audience and wrong-issuer tokens.
- Validate every routing metric. Confirm freshness, units and failure behavior.
- Replay representative traffic. Include short, long, cached, uncached and adapter-specific requests.
- Canary the gateway. Preserve a reversible route to the prior load balancer.
- Alert on routing quality. Watch tail latency, queue imbalance, cache hit rate and authentication failures.
Where it fits in the HyperPod stack
The gateway addresses live request placement. It does not replace model loading, node caching, autoscaling or application authorization. Our guide to AWS LLM latency and two different caches separates prompt-prefix reuse from model cold starts. The NVIDIA NeMo Switchyard model-router analysis shows a related reason to keep routing policy and model behavior observable as separate layers.
The practical verdict
AWS HyperPod Inference Gateway adds the right kinds of LLM-serving signals to a Kubernetes routing decision. Queue, cache and adapter awareness can be more useful than sending every request to the next pod. The first production task is still authentication: enable JWT, verify the metrics and benchmark with your own traffic before replacing a simple load balancer.
Read the primary record
- AWS HyperPod Inference Gateway documentation
- AWS HyperPod Inference release notes
- AWS launch announcement
Checked September 18, 2026. Configuration and compatibility details come from AWS documentation. Benchmark cautions and rollout advice are MustHave.ai analysis.