
ChatGPT critical-thinking study: higher rubric scores, less idea diversity without training
A 1,053-student Bocconi trial found GPT-4o access improved assignment scores while causal training produced the clearer idea-diversity gain.
What’s new. What matters. What do you think?
A 1,053-student Bocconi trial found GPT-4o access improved assignment scores while causal training produced the clearer idea-diversity gain.
WebMCP lets websites expose structured actions to browser agents. The experimental interface can reduce brittle clicking but expands the site's permission boundary.
Loading comments…
Anthropic's automated researchers improved ten measured alignment failures, but a separate monitor excluded cheating in 39 of 1,601 trajectories.
Loading comments…
Anthropic's Model Hardware Standard gives agents a common interface for lab and manufacturing devices. The evidence is promising, but MHS remains a closed preview.
Loading comments…
A federal court vacated the Pentagon's Anthropic blacklist and contractor directive. The order still leaves lawful provider transitions open.
Loading comments…
NVIDIA says Jetson Orin Nano 2 doubles inference performance and cuts matched-performance power 40%, but hardware is not due until 2027.
Loading comments…
OpenAI reports up to 1.9x more work per watt and 3.6x lower latency for Jalapeño. The public benchmark was run collaboratively in OpenAI's lab.
Loading comments…
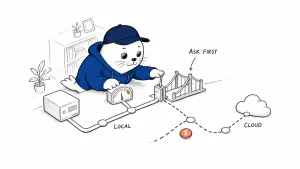
Perplexity Portable Computer and Apple's M5 Ultra Mac Studio make local agents practical. Measure utilization, escalation and accepted-task cost.
Loading comments…
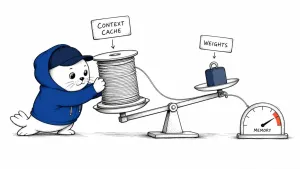
IBM Granite 4.2 adds open 3B, 8B and 30B reasoning models. The practical test is memory and accepted tasks at fixed context lengths.
Loading comments…
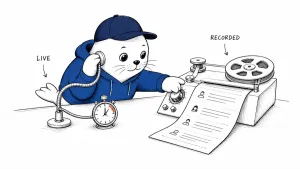
Gemini 3.5 Transcribe has separate live and recorded APIs. Compare latency, diarization, WER, preview risk and cost per accepted transcript.
Loading comments…
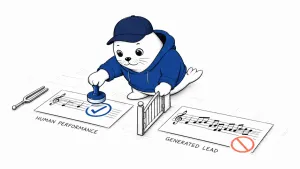
ARIA's new chart rule follows the primary performance: AI-assisted production can qualify, while generated lead vocals and instruments cannot.
Loading comments…
Hugging Face reports 2.96 million public model repos and rising agent traffic. The download distribution still measures activity, not model quality.
Loading comments…
Loading comments…