Grok 4.7 Launches With 500K Context and Two-Tier Pricing
Grok 4.7 adds a 500K context window, image input and pricing that doubles above 200K tokens. See API, Fast, Copilot and testing details.
Frontier models, comparisons, and how to choose what fits your work.
Grok 4.7 adds a 500K context window, image input and pricing that doubles above 200K tokens. See API, Fast, Copilot and testing details.
Xing4.0-29B-A4B is China Telecom's Apache-2.0 coding model with 29B total parameters, 4B active per token and a native 256K context window.
Qwen-Image-2.1 generates transparent 2K images and edits up to 10 references, but its research license bars commercial use without permission.
Step 5 Preview now has inspectable weights and serving configurations. This update corrects the earlier release forecast and explains the StepFun license boundary.
Grok Voice Transcribe 2.0 adds batch and streaming transcription, diarization, eight channels and low hourly pricing. One version discrepancy matters.
Qwen3.8-Omni-Flash accepts text, image, audio and video in a 1M-token context. Here is what ships, what does not, and what teams should test.
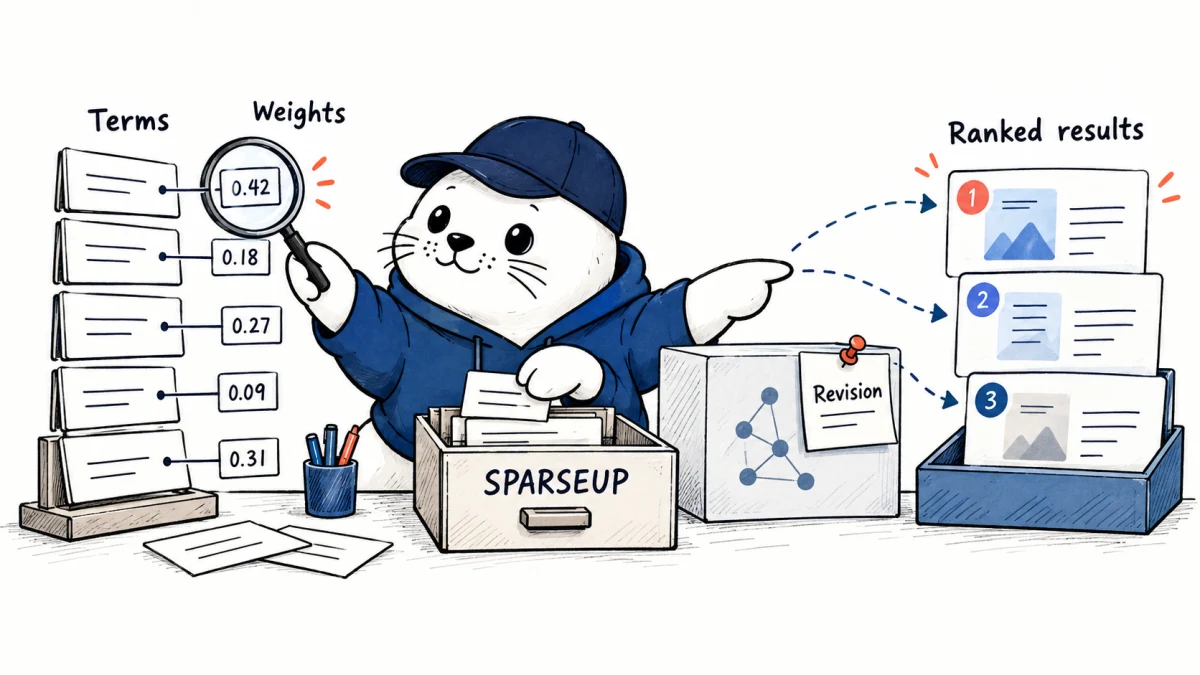
The SPARSEUP sparse retriever maps queries and documents to weighted vocabulary terms. See its 149M design, benchmarks, failure modes and RAG test plan.
Tencent EVIE open-sources 4.5B and 8B visual document retrieval models. Learn how Prefix-MRL and HAC trade index size against retrieval quality.
Atria Dawn Preview is a massive 256K text model with Codex and Claude Code setup guidance. We separate its base size, artifact size and…
Tencent WeVisDoc turns document page images into Markdown, tables and math. See the model sizes, benchmark boundaries, deployment path and tests to run.
Pareto 26.9 is the model behind the Union Alpha reveal. We separate the confirmed price and context from claims about composition, quality and adoption.
Bonsai 2 27B compresses Qwen3.8 27B into a 5.95 GB GGUF. Here is what the file size proves, what it does not, and how…