xAI released Grok 4.7 on September 21 with a 500,000-token context window, image input and a price break that changes when a prompt crosses 200,000 tokens.
Grok 4.7 is now listed in xAI’s API release notes and is also rolling out through GitHub Copilot. The practical story is not only a new model name. Developers need to understand the two-tier input pricing, the difference between standard and Fast access, and the fact that xAI has not published a system card with the launch materials reviewed by MustHave.ai.
Grok 4.7 at a glance
| Field | Published detail | Operational consequence |
|---|---|---|
| Context | 500,000 tokens | Long repositories and document sets fit, but prompts above 200,000 tokens cost more |
| Inputs | Text and images | Visual analysis can share one request with written context |
| Output | Text | No image generation in the model description |
| Reasoning | Low, medium, high and xhigh | High is the default, so latency and cost testing matters |
| Standard price below 200K | $2 input, $0.50 cached input, $6 output per million tokens | Cached context can materially lower repeat-request cost |
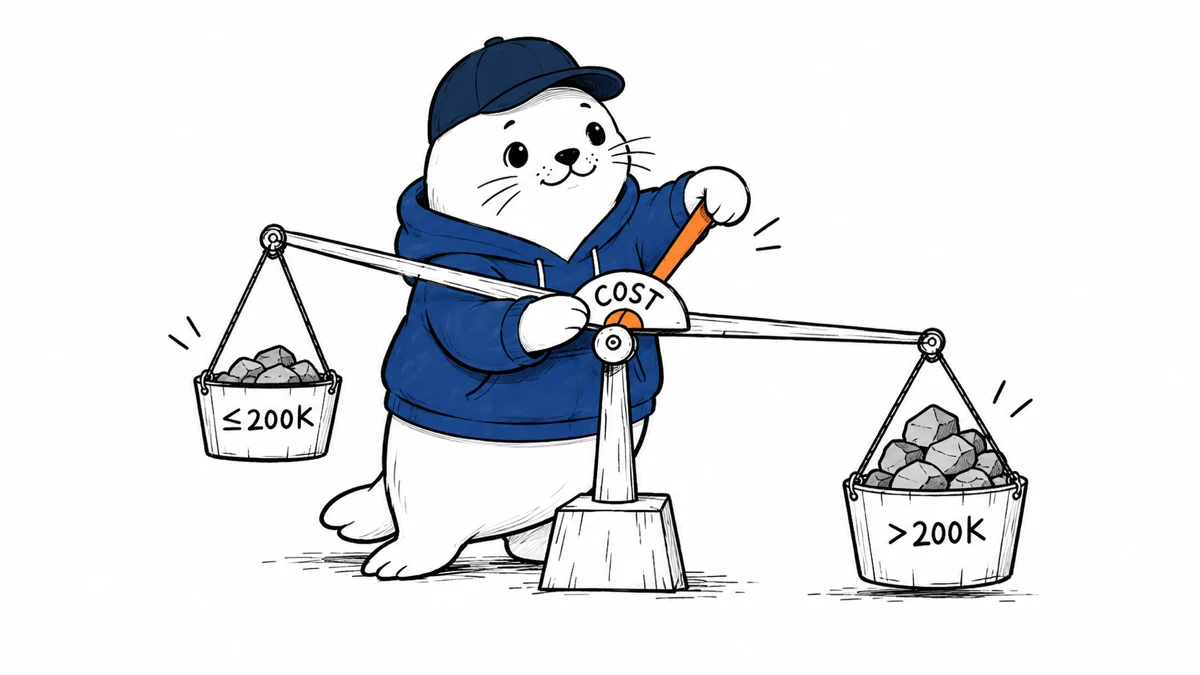
| Standard price above 200K | $4 input, $1 cached input, $12 output per million tokens | Crossing the threshold doubles all three rates |
The 200K boundary matters more than the headline context window
A 500K window invites teams to send everything. That is often the wrong default. A request with 199,000 uncached input tokens costs about $0.398 before output. A 201,000-token request is priced at the higher tier and costs about $0.804 before output. Two thousand extra tokens can therefore add roughly forty cents because the request crosses the published boundary.
The safer design is to measure how much of the context the model actually uses. Retrieve the smallest authoritative set, cache stable prefixes and reserve the larger tier for tasks that demonstrably improve with it. Our AI agent cost-controls guide explains how spend caps and routing rules turn that principle into production policy.
Standard Grok 4.7 and Grok 4.7 Fast are not the same offer
xAI says Grok 4.7 Fast is available through Cursor and Grok Build, not through the public xAI API at launch. The company describes it as delivering about twice the token rate and charges twice the standard token prices. That makes Fast a latency purchase, not a universally better model tier.
- Use standard access for background analysis, batch review and workflows where queue time is acceptable.
- Test Fast for interactive coding or agent loops where model latency blocks a person or another tool.
- Compare cost per completed task, not tokens per second in isolation.
- Do not promise public-API availability for Fast until xAI documents it.
GitHub Copilot is adding Grok 4.7 gradually
GitHub says Grok 4.7 is rolling out in Copilot and may not appear for every account at once. Availability can also depend on plan and administrator policy. Teams should treat a model picker entry as an access signal, not proof that every organization member has the same entitlement or data controls.
For repository work, compare Grok 4.7 with the models already approved by your organization using the same issue set. Our coding-agent comparison guide provides a framework for evaluating patch quality, test discipline, review burden and recovery behavior rather than relying on a single benchmark.
Vercel is discounting AI Gateway access through September 27
Vercel lists Grok 4.7 in AI Gateway and announced a 40% promotional discount through September 27, 2026. Promotional pricing is temporary. Architecture decisions should use the normal rate as the baseline and treat the discount as a short evaluation window.
A gateway can simplify provider switching, observability and keys, but it adds another control plane. Record the provider model identifier, gateway route, reasoning level, cache behavior and fallback policy for every evaluation so a later result can be reproduced.
What xAI has not documented with this release
xAI publishes benchmark claims on the launch page, but MustHave.ai did not find a Grok 4.7 system card linked from the release materials reviewed on September 22. That leaves important questions about evaluation methodology, safety testing, failure modes and deployment guidance. Company-reported benchmark positions should be labeled as such until the underlying protocol can be inspected or independently reproduced.
A production test plan for Grok 4.7
- Choose 30 real tasks split across short, medium and above-200K prompts.
- Freeze tool permissions, system instructions and temperature settings.
- Run low, medium, high and xhigh reasoning on a representative subset.
- Record input, cached input, output, latency, retries and reviewer corrections.
- Test a retrieved-context version against a full-context version.
- Calculate cost per accepted task at normal pricing.
- Audit unsupported claims, missed constraints and image-reading errors separately.
- Keep Fast out of forecasts unless the production access path is confirmed.
Primary sources
- xAI: Grok 4.7 announcement
- xAI developer release notes
- GitHub: Grok 4.7 in Copilot
- Vercel: Grok 4.7 on AI Gateway
Checked September 22, 2026. Prices and availability can change. Benchmark and speed claims remain vendor-reported.