ServiceNow AutoSynthData: why synthetic agent tasks need strong verifiers
ServiceNow’s AutoSynthData work describes a way to generate training tasks around agent failures. The useful lesson is that a generated task needs a trustworthy…
Frontier models, comparisons, and how to choose what fits your work.
ServiceNow’s AutoSynthData work describes a way to generate training tasks around agent failures. The useful lesson is that a generated task needs a trustworthy…
Clef now has Ollama local and cloud access paths. Check runtime versions, model tags, context limits and probability calibration before choosing a deployment.
Gemini 4 Argon API access, pricing and output limits, plus a downloadable 18-check coding fixture pack with an explicit testing method.
GPT-6.1 Sol is in the API, ChatGPT Work and Codex, but not Chat. Here is what its token rates mean for cached and long-context…
H Company released Holo4 models for GUI, code and API work. The 27B checkpoint is downloadable, but its license and benchmark caveats matter.
Anthropic has launched Sonnet 5.5 at Sonnet 5's token rates. GitHub Copilot is adding it too. Compare the real costs, rollout limits and migration…
Laya is available in Dell's Enterprise Hub, but its published speed and Jev comparison do not establish a universal winner.
Gemini 3.8 TTS remixes existing voices into separate stored IDs. Compare persistent voice changes with per-turn delivery and dated output prices.
Taste-Bench AI agents face 502 real decision forks from engineering and research trajectories. The best reported score is 59.7 percent under paired-order testing.
Claude Opus 5.5 lowers token and cache-read prices while targeting Fable-level work. See costs, benchmarks, access and a safe upgrade plan.
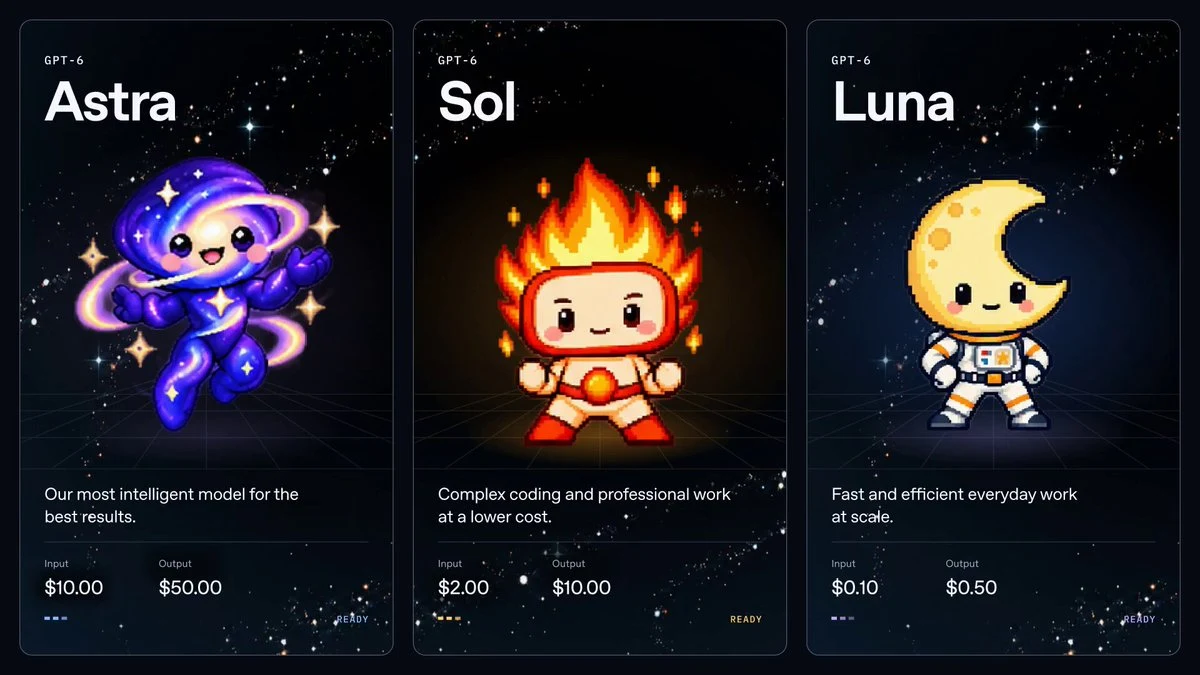
GPT-6 Sol Luna models bring lower API prices, improved caching and wider Codex access. Here is how builders should compare and route them.
Microsoft RetroChimera combines reaction prediction and route ranking for small-molecule synthesis. See study results, open code, limits and review steps.