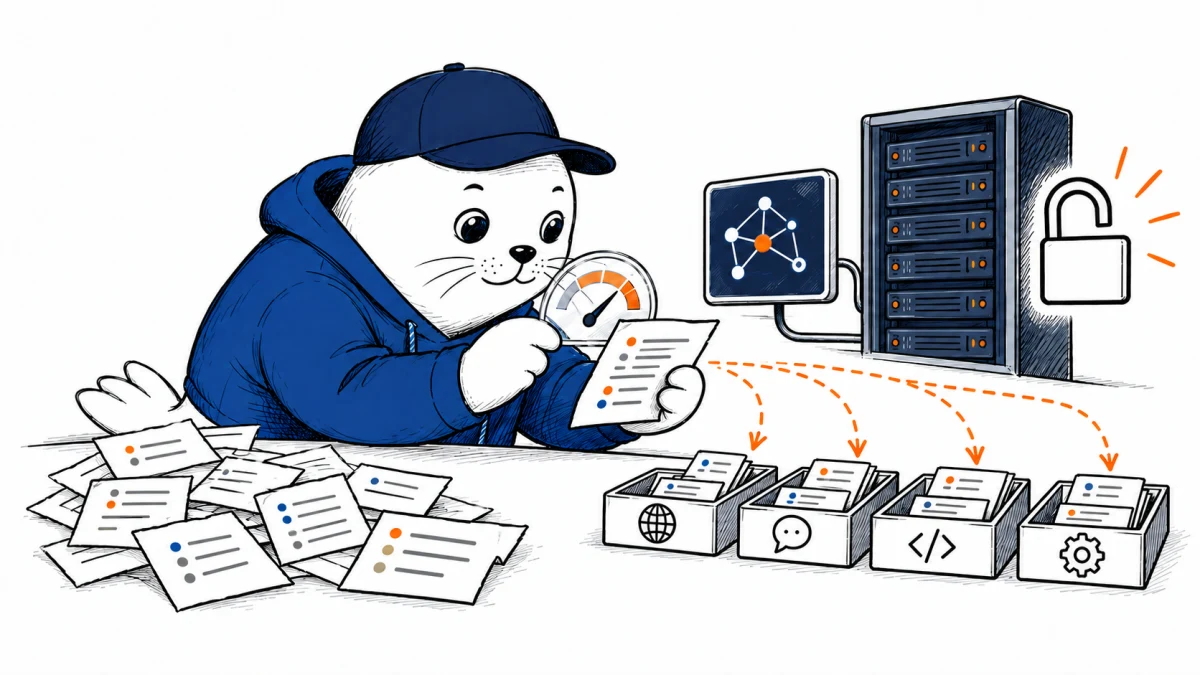
Not every AI task needs a paragraph of generated text. A support ticket may need a department, an urgency score, and a churn probability. Laya, now listed in the Dell Enterprise Hub by Hugging Face, targets that narrower decision layer. Its public benchmark claims are interesting, but they don’t provide an independent verdict against Jev.
What is actually available
The Dell Enterprise Hub listing describes Laya as a 421-million-parameter, Apache 2.0-licensed model and lists seven compatible Dell hardware configurations. Its published model family includes an English checkpoint, a 322-million-parameter multilingual checkpoint, and a checkpoint fine-tuned for typed decisions. The model takes a state and questions with specified answer types, then returns structured choices, scores, or probabilities rather than free-form prose.
That makes it a candidate for ticket routing, guardrails, and similar high-volume decisions where a JSON-shaped answer matters more than fluent writing. Dell’s listing supports the availability claim; it does not, by itself, establish how well Laya will work on a buyer’s data or hardware.
The Jev comparison needs an asterisk.
Laya’s model card compares its results with TypeSafe’s Jev, another model for typed decisions. The card explicitly says the Jev figures came from third-party published measurements and that the authors did not have TypeSafe API access for a same-run test. The prompts, samples, and setup differ. Consequently, a simple “Laya beats Jev” headline would overstate the evidence.
The card also reports trade-offs that a marketing summary could hide. Its fine-tuned typed-decisions checkpoint reaches 0.766 accuracy on the reported test, while its base English checkpoint reaches 0.362 on the same decision set. On a 77-label banking task, the card reports Laya at 0.425 versus a published Jev result of 0.870 on 72 labels. These are vendor-reported, non-identical comparisons, but they warn against assuming either universal zero-shot strength or suitability for a large menu of choices.
Speed is not the only operational question.
The Laya card reports tens-of-milliseconds single-question latency on a Tesla T4 and describes multilingual routing. Treat those numbers as a starting hypothesis, not a service-level promise. A real deployment adds input processing, queuing, network overhead, and application checks. The card also says the models can be overconfident without temperature calibration and that a returned action probability is not yet a useful signal. A product that makes consequential decisions should test calibration, not merely top-choice accuracy.
A fair buyer test
Build a held-out set from your actual ticket or policy workflow. Define the same schema and labels for Laya and Jev, and record accuracy, calibration, abstention behavior, and end-to-end latency on the same cases. Include long inputs, multiple languages, and large choice sets if those occur in production. Keep the test’s training split separate from the evaluation split; otherwise, a fine-tuned model can look better than it generalizes.
For self-hosted trials, also assess access control and deployment configuration. Laya’s model card notes that its optional HTTP server binds to all interfaces without authentication unless you configure an API key. That is an operational setting to fix before a networked evaluation, not a reason to reject the model outright. The cost-controls guide shows why infrastructure expense should be divided by accepted decisions, not compared with an API’s token price alone.
What the Dell listing changes
The noteworthy news is that an open-weight typed-decision model has a documented route into Dell’s on-premises AI catalog. That gives teams another architecture to test when privacy or predictable per-decision cost favors local inference. It does not settle the Laya-versus-Jev question. The responsible next step is a reproducible comparison against the decisions your application actually makes.