Fastly launched AI Runtime Control and AI Firewall on September 21, 2026, giving teams one control point for model routing, virtual keys, budgets and prompt-attack screening.
The headline promise of the Fastly AI Firewall is straightforward: inspect traffic before it reaches a model and inspect the answer before it returns to an application. The operational details are more useful. Streaming responses are not inspected after generation, token-based limits are best effort, and some protective transformations can add tokens that the model provider bills. Those boundaries decide where this product fits in a real architecture.
What Fastly released
| Capability | What it does | What the team still owns |
|---|---|---|
| AI Runtime Control | Routes model calls through one endpoint | Provider selection, failover policy and quality tests |
| Virtual keys | Separates applications from provider credentials | Key lifecycle, ownership and incident response |
| Budgets and limits | Tracks usage and can restrict spending or request volume | Cost attribution and hard external billing limits |
| AI Firewall | Evaluates requests and non-streaming responses | Application authorization and downstream validation |
The firewall sits on both sides of a normal response
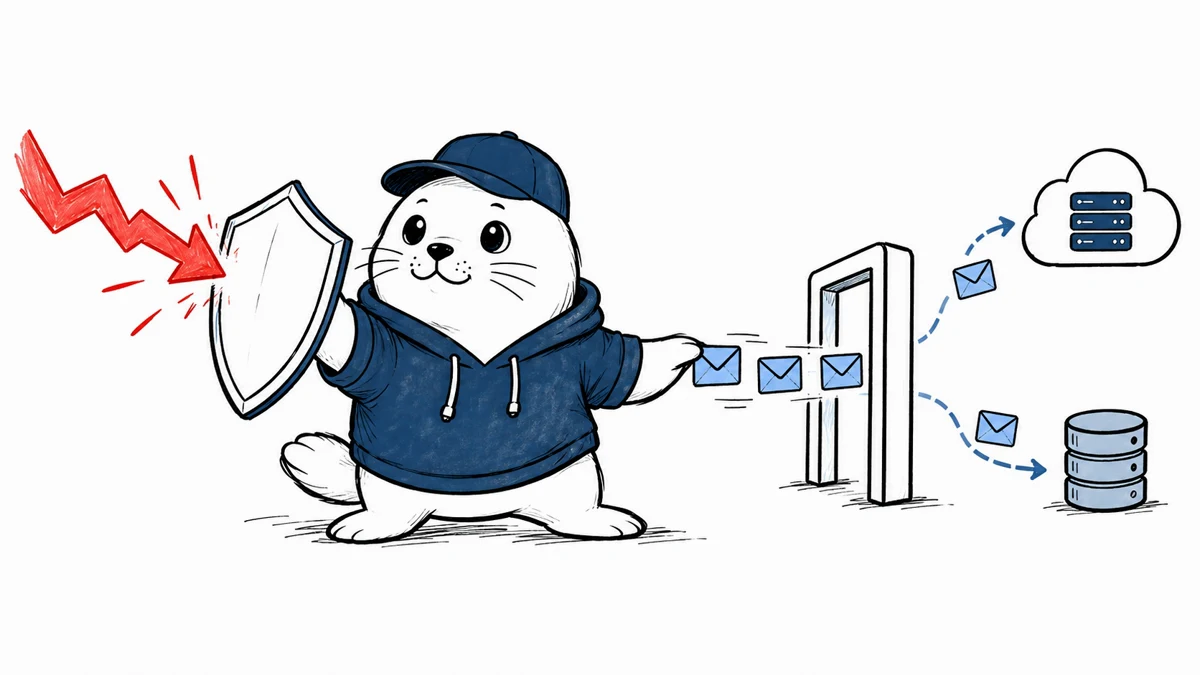
Fastly documents a request inspection step before forwarding traffic to the selected provider. A policy can log a detection or block the request. For ordinary non-streaming calls, the response can also be checked before it reaches the application. That second inspection matters when a model may expose secrets, produce unsafe content or follow malicious instructions embedded in retrieved material.
This does not replace the application’s permission checks. A firewall may recognize a suspicious prompt, but it does not know whether a particular employee should read a customer record or whether an agent is allowed to approve a purchase. Our guide to keeping package credentials away from AI tools shows why isolation and least privilege still have to exist behind the screening layer.
Streaming creates a visible inspection gap
Fastly says streaming requests are proxied without response inspection. That is an important design choice, not a footnote. Streaming improves perceived latency because tokens reach the user immediately, but the gateway cannot hold the complete answer for a final decision.
- Use response inspection for workflows where blocking a complete unsafe answer matters more than first-token speed.
- If streaming is required, add output validation inside the application and restrict what streamed text can trigger.
- Never allow streamed model text to become a tool command without a separate structured authorization step.
- Log the policy mode and request type so investigators can distinguish inspected from uninspected responses.
Token limits are not the same as a billing hard stop
A gateway knows the input size before sending a request, but the final output-token count is available only after the response. Fastly therefore describes token-based rate limits as best effort. A long answer can cross a threshold before the system has the final count. Provider invoices also remain authoritative.
Production controls should combine request limits, provider-side budgets, application quotas and alerts. The calculation framework in our AI agent cost-controls guide helps teams turn per-token prices into completed-task limits rather than relying on a gateway counter alone.
Structural isolation can change the token bill
Fastly’s documentation notes that structural isolation can add content to a prompt. That extra material is intended to separate trusted instructions from untrusted input, but the provider may count it as input tokens. Teams should measure the size of those additions on short prompts, where fixed overhead is proportionally largest, and on cached prompts, where transformations may affect cache reuse.
A practical rollout plan
- Inventory every model endpoint, key owner and current fallback.
- Place one low-risk application behind Runtime Control in log-only mode.
- Compare provider identifiers, latency, token counts and failure behavior before and after routing.
- Test direct prompt injection, indirect injection from retrieved documents and secret-recovery attempts.
- Run separate tests for streaming and non-streaming responses.
- Set application, gateway and provider budgets independently.
- Verify that a blocked request produces a safe user message and an actionable audit event.
- Document a bypass and rollback path before expanding traffic.
What the launch does not prove
Fastly reports that machine traffic now exceeds half of observed traffic and that AI traffic is growing faster than human traffic. Those are company-reported measurements, not an independent internet-wide census. The launch also does not prove that every prompt attack will be recognized, that every provider behaves identically, or that a gateway can replace application authorization. Buyers should judge the product through their own attack corpus and failure scenarios.
Primary sources
- Fastly launch announcement
- Fastly AI Runtime Control product page
- How AI Runtime Control works
- Fastly virtual-key documentation
Checked September 22, 2026. Availability, limits and product behavior can change. Traffic metrics remain company-reported.