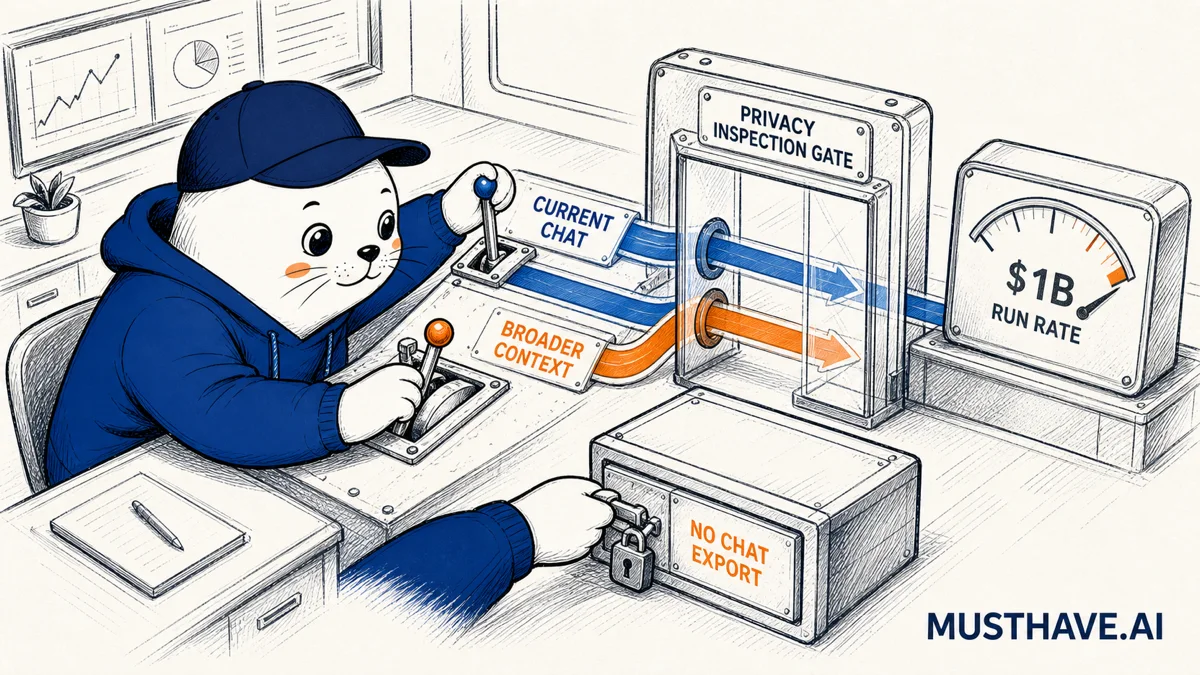
OpenAI says ChatGPT Ads hit a $1B run rate. Targeting is the bigger story
OpenAI says ChatGPT Ads reached a $1B annualized run rate. The sharper questions concern conversation context, custom audiences and measurement.
I'm Abdessalam Alaoui, founder of Musthave.AI. I write practical guides to AI models, tools, generative media, and ways real people make money with this stuff. No press-release fluff. 20+ years shipping digital products; you'll also find my work around HowTik, Yumasty, and IncomeHelpful.
OpenAI says ChatGPT Ads reached a $1B annualized run rate. The sharper questions concern conversation context, custom audiences and measurement.
GitHub Copilot Memory and Ollama support are in JetBrains 1.15. Here is how memory scope, expiration, admin controls, and local-model claims work.
MAI-Code-1.1-Flash brings image input and a 0.25× Copilot request multiplier. Teams have until September 10 to retire the old model.
Google's SL2T turns ASL into English text on Pixel 11. Here is what runs on device, what reaches Google's servers, and where errors still…
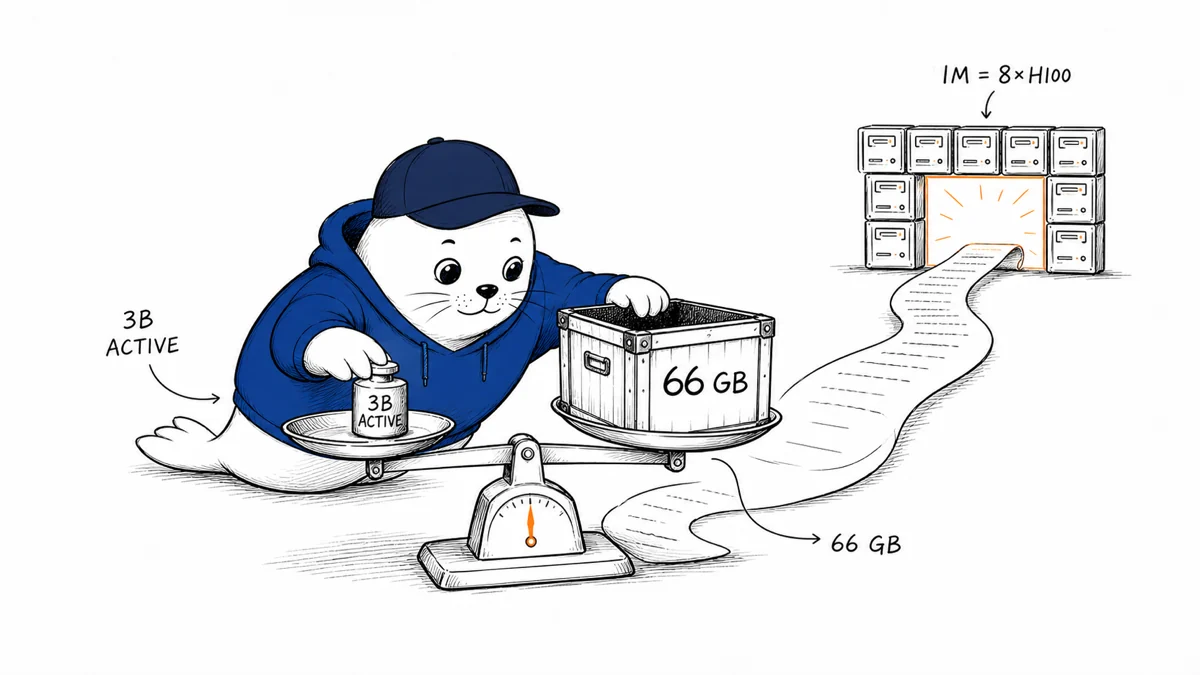
NVIDIA's Nemotron 3.5 Lightning activates 3B of 30B parameters, but the BF16 weights are about 66 GB and one-million-token context needs serious hardware.
Spotify will label some AI-generated artist identities and remove them from default recommendations. The badge does not explain how every song was made.
Anthropic expands text watermark support to older Claude models. Sonnet 4.6 sampling settings can affect the signal, while detector access remains restricted.
DeepSeek Flash 1017 is now on Workers AI. Compare provider prices, access requirements and rate limits separately from native API pricing and Fireworks training.
Claude improved a lower bound related to simple Riemann-zeta zeros. The paper, expert checks, transcripts, and Lean files matter more than the viral percentage.
Meta Muse Glimmer offers a 17 GB package for 24 GB devices. Builders still need to test runtime support, context memory, and tool-loop reliability.
SHE turns unsafe agent trajectories into bounded safety-harness edits. Its held-out test matters more than the self-editing demo.
OpenAI's GPT-5.6-Cyber attempts far more advanced security work. Here is when Daybreak Red is justified and which controls must replace refusals.