TypeSafe AI has emerged from stealth with a $40 million seed round and Jev, an early-access model built to return typed, probabilistic decisions instead of open-ended text. The design could make some automation faster and easier to validate, but its most dramatic performance claims still come from the company’s own evaluation system.
October 2 update: Jev arrives in Replit AI Integrations
Replit’s October 2 changelog lists Jev in AI Integrations. Replit describes this integration as removing the need to manage a separate provider API key.
For teams already building on Replit, this adds an implementation option. It does not establish that Jev’s decisions are accurate on a particular workload. Test semantic accuracy and confidence calibration with representative examples before allowing automated decisions to affect customers.
Source: Replit’s October 2 changelog.
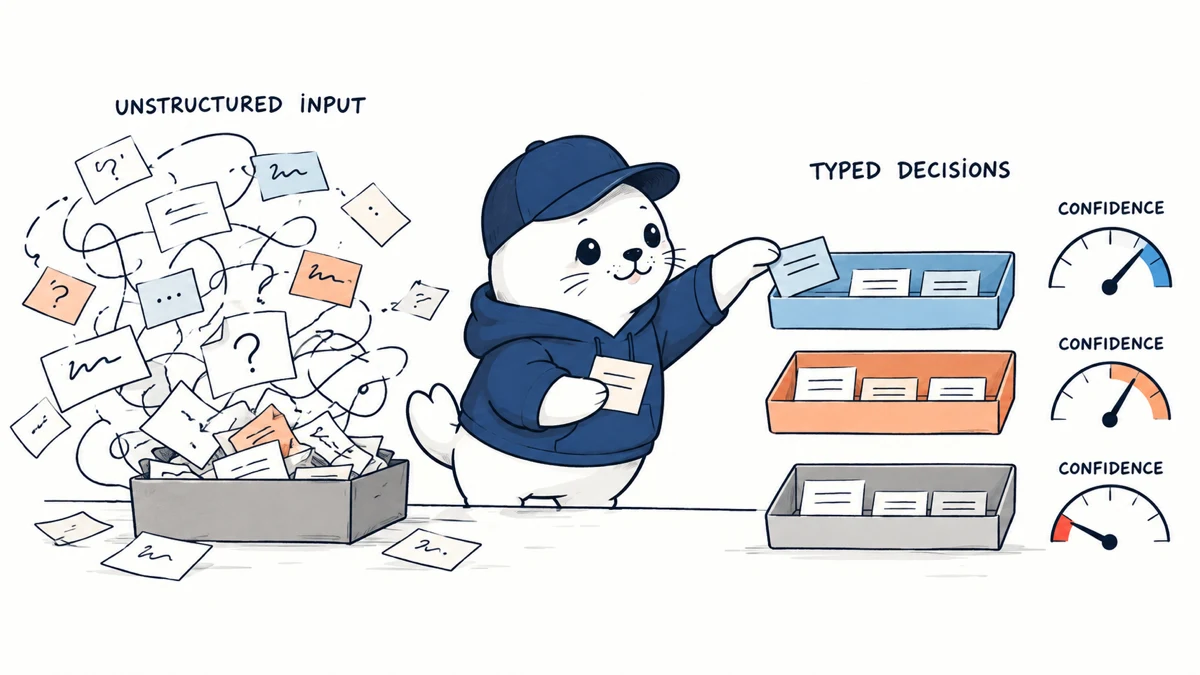
DCVC confirmed that it led the unusually large seed investment. TypeSafe says Jev is the first of its “System One Models,” a category optimized for fast decisions inside software workflows. The pitch is narrower than replacing a general-purpose large language model: send unstructured state, define the permitted output types in advance, and receive a set of decisions with probabilities and confidence scores.
September 22 update: Jev gets a native Vercel AI Gateway API
Vercel added first-party Jev support to AI Gateway. Developers can point the TypeSafe client at the gateway with a base URL and gateway API key, or call a native /v1/evaluate endpoint with the model identifier. typesafe-ai/jev.
| Integration path | Published behavior | Reason to use it |
|---|---|---|
| TypeSafe client | Change the base URL and authentication key | Move an existing Jev integration behind gateway billing and observability |
| HTTP evaluate endpoint | Call /v1/evaluate with typesafe-ai/jev | Use Jev without adding a provider-specific client |
| Decision types | Boolean, choice and score are documented | Keep downstream software on bounded outputs |
| Existing primitive | Noul remains part of the model’s native vocabulary | Preserve Jev’s typed-decision framing |
The update reduces integration work, but it does not change Jev’s correctness boundary. Teams should still measure schema validity, calibration, false positives, and downstream decision cost on their own workload. Gateway telemetry and unified billing improve operations; they do not independently validate the model.
Source: Vercel’s Jev AI Gateway changelog. The announcement also says eve uses Jev as a default evaluator, which is an adoption signal inside Vercel’s agent tooling rather than a universal recommendation for every decision task.
September 20 update: Jev adoption on Vercel AI Gateway
Vercel has now published platform telemetry for Jev’s first days on AI Gateway. The company says Jev reached more than twice as many paid teams as any previous model launch in its first 24 hours and nearly 13 percent of paid teams by hour 24.
| Vercel measure | Published share | What it represents |
|---|---|---|
| Requests | 26.3 percent | Share of calls routed through the measured gateway window. |
| Team reach | 15.6 percent | Share of measured teams that used Jev. |
| Primary-model preference | 13.3 percent | Share of teams treating Jev as their primary model. |
| Token volume | 1.8 percent | Share of tokens processed, not share of requests. |
These are anonymized Vercel platform measurements current through September 18 and 19. They are not an independent quality benchmark and do not measure the whole AI market. The large gap between request share and token share is directionally consistent with Jev’s role as a compact typed-decision model, where one call may return a short structured result rather than a long generated answer. That interpretation is an inference, not a measurement Vercel published.
For buyers, the update changes the adoption signal, not the correctness standard. A high number of short calls can make request share look dramatic while using relatively few tokens. Compare cost per accepted decision, schema validity, calibration, and downstream error rate rather than request count alone. Sources: Vercel’s Jev launch analysis and the Vercel AI Gateway model leaderboard.
Why Jev is suddenly drawing attention
TypeSafe officially introduced Jev on September 15, 2026, after two years in stealth. The model is available in early access, not general availability. TypeSafe calls it the first public “System One Model,” a category designed for rapid decisions inside software rather than conversation or long-form generation.
The launch is unusual because Jev deliberately avoids generating free-form text. An application sends unstructured state, declares the decisions it needs, and receives typed answers with probabilities. The current API exposes three decision primitives: Noul for a yes probability, Choice for selecting among named options and Score for placing an answer on a defined scale.
The new training claim is RLCD.
TypeSafe says Jev uses a training method called Reinforcement Learning for Calibrated Decisions, or RLCD. The goal is not to reward persuasive prose. It is to make probabilities better reflect how often a decision is correct. That distinction matters in automation because a system can route uncertain cases to a human instead of pretending every answer is equally reliable.
Jev’s schema guarantee prevents malformed output and invalid types. It does not guarantee that every valid decision is factually or operationally correct. A ticket can be routed to an allowed department and still be routed to the wrong one. Production buyers should therefore test semantic accuracy, calibration, and the cost of false decisions separately.
The headline numbers need their conditions.
TypeSafe lists input pricing at $0.042 per million tokens and says output is free because it is too inexpensive to meter. The company reports response times from 70 to 500 milliseconds and says Jev can be 40 to 200 times faster on System One-shaped tasks. Its published workflow evaluation produced larger figures: 193.6 times faster and 444.6 times cheaper.
Those are company-reported results, not independent benchmark findings. TypeSafe says its capabilities team created the workflow tests, used the average of Astra and Fable as reference probabilities, and likely represents the high end of real-world gains. The launch post also acknowledges that long-term pricing sustainability has not yet been demonstrated.
Developers can inspect the official Jev launch announcement and the TypeSafe API quick start. Marker: jev-system-one-launch-news-20260918.
September 18 update: Jev gets an official LangChain integration
LangChain has now published an official integration for Jev, turning the model from an unusual API into something developers can place directly inside an agent harness. The langchain-typesafe package exposes TypeSafeClassifier, which accepts the state an agent already has and returns typed classification results instead of generated prose.
The key distinction remains the same: Jev is not a chat model and cannot replace the model that writes code, explanations, or customer replies. It handles bounded decisions. LangChain shows three practical jobs for it: choosing between a cheaper and a more capable model, classifying a request, and checking a proposed tool call before execution.
The guardrail pattern is the most interesting addition
LangChain’s experimental AutoModeMiddleware can use Jev to judge whether a tool call looks risky and block it before the tool runs. That does not make an agent safe by itself. A classifier can still be wrong, and a security boundary should not depend on one probability. The useful pattern is layered: Jev provides a fast decision, a deterministic policy handles hard prohibitions, and a human approves actions with a large failure radius.
Model-routing middleware uses the same idea for cost control. A team can define a fast route for extraction or localized edits and a stronger route for architecture or high-stakes work. Jev chooses among the allowed options and leaves its probability and confidence in agent state. That makes the route observable instead of hiding it inside a prompt.
TypeSafe says Jev can be up to 193.6 times faster and 444.6 times cheaper in its published workflow evaluations. Those are company-reported results, produced on TypeSafe’s own workflows and compared with external models through its harness. The company also says the numbers sit near the high end of expected real-world gains. Jev remains in early access, accepts text rather than images, audio, or video, and gives up free-form generation in exchange for typed outputs.
What to test before putting Jev in a production loop
- Build a labeled set from the exact decisions your agent makes, not a generic benchmark.
- Measure false allows and false blocks separately because their costs are rarely equal.
- Choose thresholds from the consequence of the action, then keep a deterministic deny list outside the model.
- Log the input state, selected route, probability, confidence, and outcome for later review.
- Retest after changing criteria, middleware, agent prompts, or the model alias behind
jev-latest.
Read LangChain’s Jev harness guide, the LangChain TypeSafe integration, and TypeSafe’s quick start.
Update checked September 18, 2026. Product behavior comes from LangChain and TypeSafe documentation. Testing and deployment recommendations are MustHave.ai analysis. Marker: jev-langchain-harness-20260918.
Jev changes the output contract.
A conventional language model produces a sequence of tokens. Even when a developer requests JSON, the application normally has to parse the response, validate the schema, and decide what to do when the output is malformed. Jev replaces free-form string generation with a predefined typed space.
| Design question | General-purpose LLM | TypeSafe Jev |
|---|---|---|
| Primary output | Generated text or structured text | Typed decisions defined by the application |
| Sampling | Sequential token generation | Parallel decision outputs |
| Uncertainty | Optional and prompt-dependent | Probability and confidence included |
| Best fit | Writing, reasoning, coding and flexible interaction | Classification, routing, scoring and workflow branching |
| Main limitation | Malformed or unconstrained output is possible | No free-form string generation |
What “cannot hallucinate” actually means
TypeSafe says Jev cannot hallucinate because it cannot produce a value outside the declared type. That is a useful guarantee, but it is not the same as semantic correctness. A model can return a valid value from an allowed list and still choose the wrong value. The strongest defensible interpretation is that Jev prevents schema and type errors, while accuracy, calibration, and business impact remain empirical questions.
The published speed and price claims
TypeSafe lists input pricing of $0.042 per million tokens and says output is too inexpensive to meter. It reports end-to-end latency between 70 and 500 milliseconds and a typical 40x to 200x speed advantage for similarly shaped decision tasks. Its workflow evaluation produced larger headline figures: 193.6x faster and 444.6x cheaper.
Those numbers need boundaries. TypeSafe created the workflows, used the average of GPT-6 Astra and Fable 5.1 as reference probabilities, and says the largest gains may sit at the high end of real-world results. The company also states that long-term pricing sustainability is not yet proven. This is transparent disclosure, but it does not replace independent replication.
Why the $40 million seed matters
DCVC’s investment thesis is that software will eventually make far more AI calls than people do. If that is right, the winning interface may look less like a chatbot and more like a dependable decision primitive. The funding gives TypeSafe room to build a new architecture, training method, and serving stack instead of wrapping another model API.
The round does not prove product-market fit. Jev remains in early access, and TypeSafe has not published broad production adoption, retention, or reliability data. For comparison, our Astra versus Fable coding guide examines general-purpose agent systems, while our production-systems analysis shows why application-level controls matter beyond model scores.
A five-part buyer test for typed AI decisions
- Define a decision where every permitted answer can be represented as an explicit type.
- Build a frozen evaluation set with costly edge cases and a real abstention option.
- Measure semantic accuracy and calibration, not only schema validity.
- Compare total workflow latency and cost, including retries, validation, and fallbacks.
- Run a shadow deployment before allowing the model to trigger irreversible actions.
Where Jev could be genuinely useful
The strongest initial use cases are high-volume, low-latency decisions with a bounded answer space: lead routing, content moderation labels, fraud escalation, support triage, policy checks and selecting among known tools. Jev is less obviously suited to tasks whose value comes from creating new language, exploring an open-ended plan, or explaining a nuanced conclusion.
The practical verdict
TypeSafe Jev is interesting because it questions whether text should be the default model-to-software interface. Its typed output contract can remove one failure class, and its parallel design may be attractive for large decision graphs. The next proof point is not another striking multiple. It is independent evidence that Jev’s probabilities stay calibrated and its decisions stay correct when real data shifts.
Primary sources
- TypeSafe AI: Introducing System One Models and Jev
- DCVC: TypeSafe emerges from stealth
- TypeSafe AI on GitHub
Mantic AI forecasting provides another structured-decision case: its tournament result depends on a forecasting harness, calibration, and clearly bounded scoring conditions.
Checked September 16, 2026. The lead investor has confirmed funding. Performance, pricing, and product claims are company-reported and have not been independently audited by MustHave.ai.