A trillion-parameter training test is not a trillion-parameter chatbot release.
Ai2 announced Olmo-core 3 on October 1, 2026. It is training infrastructure for mixture-of-experts models, with changes intended to reduce communication and memory overhead. Teams planning a training run should read the release as a systems result, not a model-quality leaderboard.
What changed in the training stack
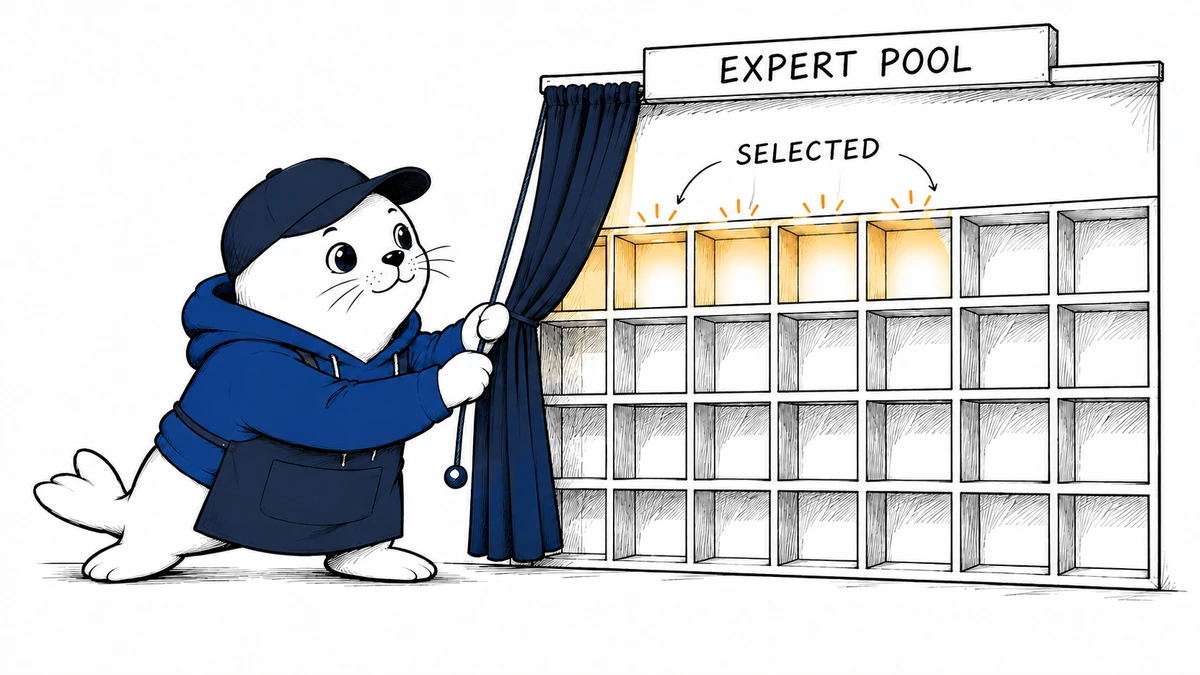
A mixture-of-experts model contains specialized components called experts. Each token uses only a selection of them. The total parameter count describes the whole model; active parameters describe the portion used for a token. Storage and communication still matter even when active computation stays smaller.
According to Ai2’s announcement, the new stack keeps experts on GPUs and sends relevant data to them. Its previous implementation repeatedly gathered and redistributed weights. On eight NVIDIA B300 GPUs, Ai2 reports 52,000 tokens per second per GPU for a 47-billion-parameter model, versus 19,400 with its earlier stack.
That comparison is roughly 2.7 times Ai2’s internal baseline throughput. It does not show a 2.7-fold improvement over every competing framework. The official repository is the place to inspect implementation and installation requirements.
Capacity is only one part of the budget.
The release also reports trillion-scale systems tests. These measure whether infrastructure can handle large configurations. They do not establish a fully trainedmodel’s reasoning ability. A brief capacity test and a complete training run answer different questions.
Before estimating savings, write down what your budget includes. Faster token processing helps only part of the bill. Data preparation, failed runs, checkpoint storage, and evaluations still cost money. A lower hourly GPU price can also hide slower networking or longer recovery times.
A readiness checklist for smaller teams
- Define the target model and active parameter count before selecting hardware.
- Check GPU memory and network requirements against the exact configuration.
- Run a short pilot with representative sequence lengths and routing behavior.
- Test checkpoint recovery after interruption, rather than timing only the healthy path.
- Reserve compute for evaluation and compare quality at a fixed training budget.
Use total cost per accepted model as the decision measure. Throughput is useful diagnostic evidence, but it cannot tell you whether a model meets your task requirements. This checklist is planning advice, not a reproduction of AI2’s benchmark.
Operational budgets also need space for logs, as our AI logging cost guide explains. Keep research and publishing claims separate using our source-review checklist.