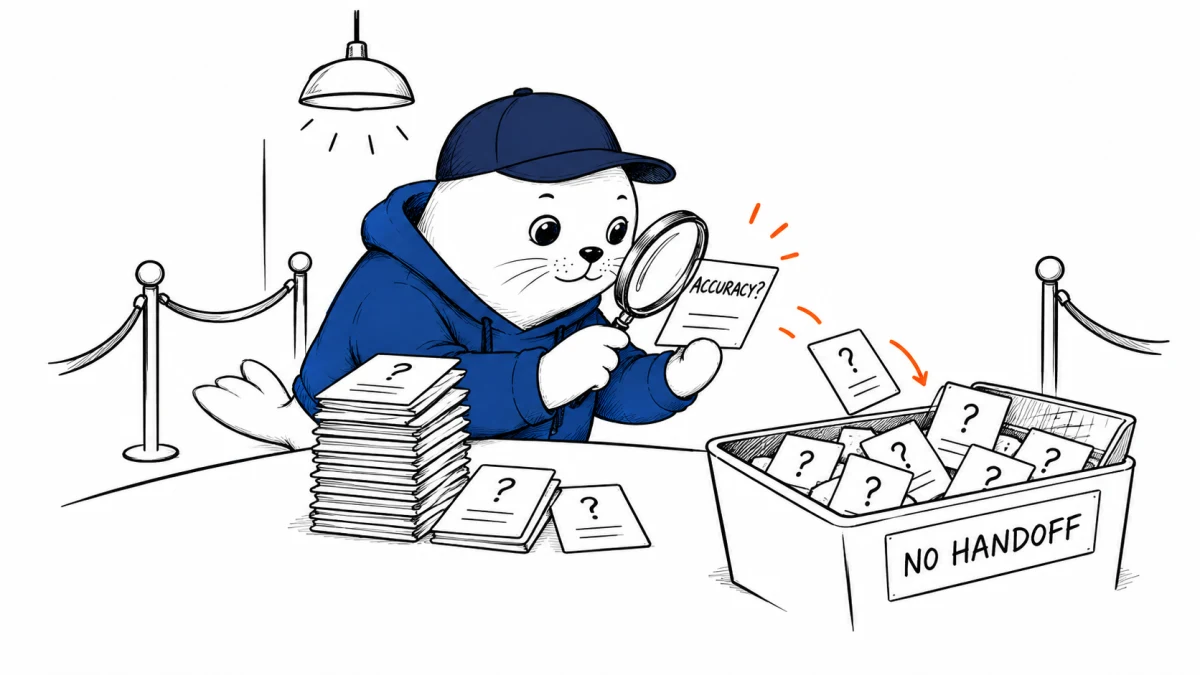
Live Nation says a Salesforce Agentforce system now resolves 95% of venue questions without handing the conversation to a human. That is a strong containment claim. It is not the same as saying 95% of answers are correct.
The distinction is essential for evaluating customer-service AI. A session can avoid handoff because the answer was useful, because the user gave up, because no escalation path was offered or because the system misclassified the request. Containment measures workflow outcome. Accuracy measures answer quality.
What Live Nation and Salesforce report
| Deployment | Company-reported result | What the number describes |
|---|---|---|
| BottleRock festival agent | Launched in under 30 days | Implementation speed |
| BottleRock | 37,000 interactions in 17,000 sessions over 12 days | Usage volume |
| BottleRock | 85% answered within three responses | Conversation length |
| Venue Agent | 95% without human handoff | Containment |
| Venue rollout | 120 sites and a projected 300,000 inquiries a year | Deployment scale and forecast |
The Live Nation Agentforce 95% figure is valuable operational evidence because it shows the agent is doing more than generating a demo answer. The missing evidence is whether customers received correct, complete and safe responses.
Why no handoff can overstate success
- User abandonment: a customer leaves after an unhelpful response and no handoff occurs.
- Hidden escalation need: the agent answers a policy question that should have been reviewed by staff.
- Partial resolution: the agent supplies general information but misses the customer’s specific constraint.
- Repeated attempts: one unresolved user can generate several contained sessions.
- Unavailable channel: the system has no accessible human path, mechanically increasing containment.
A better evaluation links containment to quality. For example, report the percentage of contained conversations that were independently judged correct and complete, then publish abandonment and repeat-contact rates.
The denominator needs to be visible
The case study says 95% of venue questions avoid handoff, but the public materials do not provide the exact evaluation window, eligible question count or exclusion rules next to that metric. Those details determine whether the rate covers all contacts, supported intents or only questions the agent accepted.
The 300,000 annual inquiries figure is described as a projection. It should not be presented as completed volume. The 120-site count indicates rollout breadth, but sites can differ sharply in traffic, question complexity and staffing.
A metrics stack for customer-service agents
| Metric | What it catches | Common failure |
|---|---|---|
| Verified resolution | Correct and complete answer confirmed by review or outcome | Sampling only easy conversations |
| Handoff rate | Work transferred to people | Treating every avoided handoff as success |
| Abandonment rate | Users who leave before resolution | Counting silence as containment |
| Repeat contact | Users who return with the same issue | Splitting one failure across sessions |
| Critical-error rate | Wrong safety, access, refund or accessibility guidance | Averaging severe errors into a broad score |
| Customer effort | Turns and time required to solve the issue | Optimizing for short answers rather than resolution |
BottleRock provides useful scale evidence
The BottleRock deployment handled 37,000 interactions across 17,000 sessions in 12 days, according to Salesforce. That is roughly 2.18 interactions per session, although the underlying distribution is unknown. The reported 85% within three responses suggests many questions were short, but it does not reveal whether long sessions were the difficult or high-risk ones.
Festival and venue questions are a good agent domain when the knowledge base is authoritative and the scope is clear: entrances, schedules, accessibility, prohibited items and venue services. The risk rises when the assistant crosses into transactions, refunds, safety incidents or individualized accessibility commitments.
How another venue can test the claim
- Define supported intents and critical intents before launch.
- Create a holdout set from real, anonymized questions.
- Have venue experts score correctness, completeness and escalation need.
- Track abandonment and repeat contact across channels.
- Review every safety, accessibility and payment error.
- Publish containment only beside verified resolution.
- Audit changes after each knowledge-base or model update.
For a wider view of Salesforce’s agent architecture, see our Salesforce AIforce analysis and our Missionforce government-agent breakdown. Both show why orchestration and governance metrics need to sit beside model capability.
The practical verdict
Live Nation’s reported scale and 95% no-handoff rate make this a meaningful production case study. The metric supports a claim about containment, not 95% accuracy. The next level of evidence would pair it with independently sampled correctness, abandonment, repeat contact, customer satisfaction and a failure taxonomy for critical venue questions.
Primary sources
Checked September 17, 2026. Performance figures are company-reported. MustHave.ai has not independently audited the deployments or answer quality.