
DeepSeek Flash 1017: Compare Native API, Workers AI and Training Limits
DeepSeek Flash 1017 is now on Workers AI. Compare provider prices, access requirements and rate limits separately from native API pricing and Fireworks training.
What’s new. What matters. What do you think?
DeepSeek Flash 1017 is now on Workers AI. Compare provider prices, access requirements and rate limits separately from native API pricing and Fireworks training.
Claude improved a lower bound related to simple Riemann-zeta zeros. The paper, expert checks, transcripts, and Lean files matter more than the viral percentage.
Loading comments…
Meta Muse Glimmer offers a 17 GB package for 24 GB devices. Builders still need to test runtime support, context memory, and tool-loop reliability.
Loading comments…
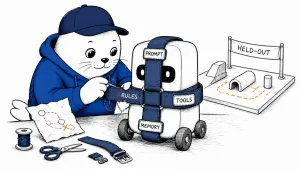
SHE turns unsafe agent trajectories into bounded safety-harness edits. Its held-out test matters more than the self-editing demo.
Loading comments…
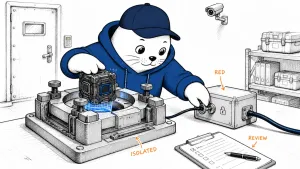
OpenAI's GPT-5.6-Cyber attempts far more advanced security work. Here is when Daybreak Red is justified and which controls must replace refusals.
Loading comments…
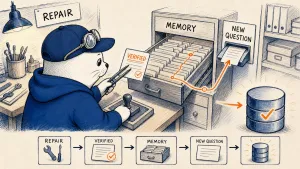
A new Text-to-SQL study separates exact replay from held-out transfer and reports that verified repairs improved later first-attempt accuracy.
Loading comments…
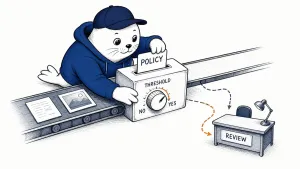
Mistral Shieldstral accepts a natural-language safety policy at inference time. Builders still have to calibrate thresholds, cost, and human review.
Loading comments…
Compare Suno’s free, Pro and Premier allowances. Separate generation credits, monthly downloads and commercial permissions before choosing a billing plan.
Loading comments…
The EU moved major high-risk AI deadlines into 2027 and 2028, while enforcement powers for advanced general-purpose models are already live.
Loading comments…
An AutoML benchmark looked decisive until its authors separated model selection from the test set and enforced equal wall-clock limits.
Loading comments…
P-Bench tests whether AI agents choose an appropriate statistical method before running R code. Fisher-R1 improves reported results, but its public artifacts are incomplete.
Loading comments…
FinRank tests whether financial QA systems retrieve evidence from the correct company, filing period, and disclosure context, not merely a plausible passage.
Loading comments…
Loading comments…