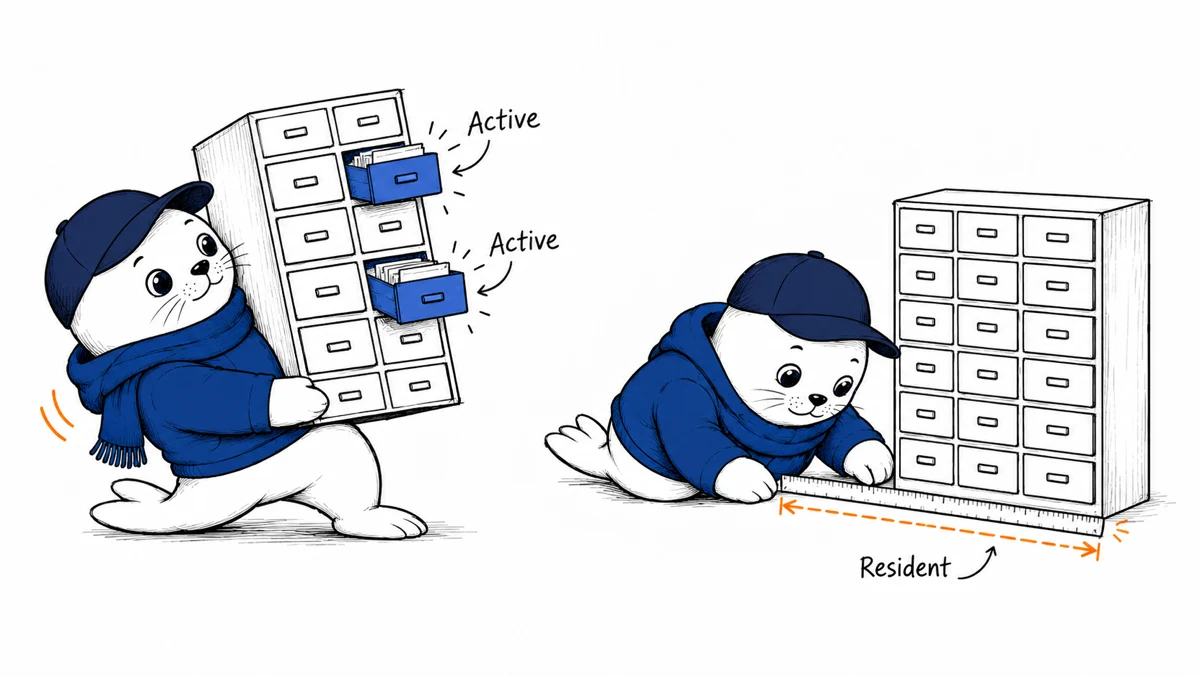
LiquidAI LFM2.5-24B-A2B: Check Memory and Tool Calls Before Running a Local Agent
LiquidAI released an open-weight reasoning model with 24 billion total and 2 billion active parameters. Test memory use and accepted tool actions on your…
Frontier models, comparisons, and how to choose what fits your work.
LiquidAI released an open-weight reasoning model with 24 billion total and 2 billion active parameters. Test memory use and accepted tool actions on your…
Microsoft plans Maia 300 production deployments in 2027. Its efficiency estimates do not yet establish customer availability or lower API prices.
Meta announced Muse Wonder and Wonder Full on October 12. Check their access paths and test remembered context separately from permission to act.
Check Nano Banana 2.1’s endpoint limits and compare edits with a fixed test. Keep model-card capacity separate from the API you actually use.
Google’s new embedding model connects text and media in a shared space. Start with a small retrieval test before adding generated answers.
GPT-6 is rolling out across ChatGPT plans. The October ChatGPT release differs from the September versions in Codex and Work.
Mistral released Large 4 weights after its API preview. The checkpoint supports three reasoning modes, and its license has a specific Model-as-a-Service condition.
Haiku 5.5 lowers token rates for routine work. Check the 100,000-token pricing boundary, recount tokens and test request compatibility before migrating.
TII announced Falcon-Emirati-7B for Emirati Arabic. Review dialect naturalness and factual correctness separately before using it in a customer workflow.
Reflection released Beam weights on October 16. Review Apache 2.0 checkpoints, serving requirements and the difference between Ollama cloud access and local use.
OpenAI announced textGrain with API opt-in and a phased EU rollout. A detected watermark gives an origin signal, not a verdict on accuracy or…
A PyTorch engineering article describes a Helion-based linear backend for vLLM. Its performance discussion is a reason to run a controlled benchmark, not a…