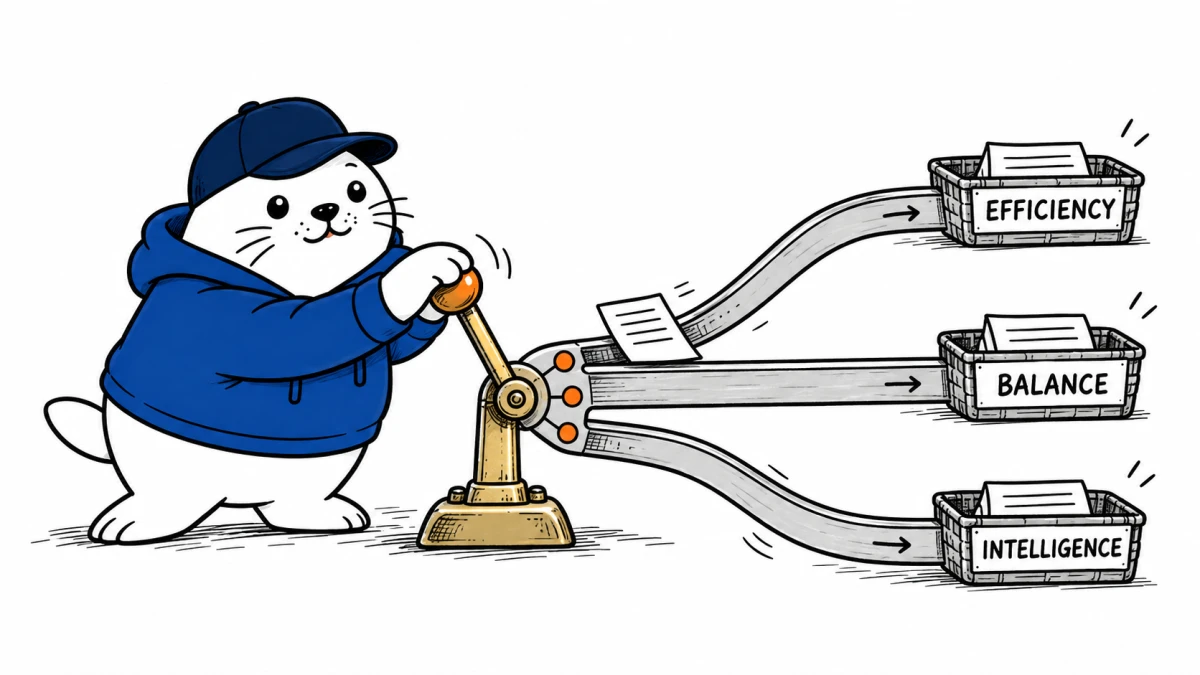
GitHub Copilot Auto now lets developers choose whether automatic model selection should emphasize lower cost, an everyday balance, or maximum quality. The new control is useful, but it is a routing policy, not a promise to use one particular model.
GitHub announced the change on September 14, 2026. The official changelog names three tiers: Efficiency, Balance and Intelligence. The feature is rolling out in Visual Studio Code, Copilot CLI and the GitHub Copilot app.
What each GitHub Copilot Auto tier changes
| Tier | Primary goal | Best first test | Main risk |
|---|---|---|---|
| Efficiency | Keep cost low and respond quickly | Docstrings, small edits and simple explanations | A cheap response can cost more if it needs repair |
| Balance | Weigh cost, quality and latency together | Everyday feature work and test maintenance | The middle policy can hide large task-to-task variation |
| Intelligence | Prioritize quality for complex work | Cross-file changes, diagnosis and architecture | Higher model cost may not improve a simple task |
Intelligence does not mean the largest model every time
All three tiers use the same available-model pool. GitHub says Auto evaluates each prompt and selects a suitable model according to the chosen trade-off. Its own example says an Intelligence-tier request for a simple docstring can still go to a small efficient model.
That distinction matters for reproducibility. A fixed model name describes one dependency. Auto describes a policy whose result can vary with the prompt, model availability and GitHub’s routing logic. Teams should log the selected model when the product exposes it, along with the tier, task class, elapsed time and outcome.
Billing follows the selected model, not the tier label
GitHub says usage is charged according to the model Auto selects, regardless of tier. Paid subscribers continue to receive a 10 percent discount on usage billed through Auto. A tier therefore does not create a flat price.
The useful metric is cost per accepted task: total model charges plus the value of developer review and repair, divided by tasks that pass the team’s acceptance gate. Price per prompt misses retries, reverted patches and extra review time.
A 12-task test that reveals the real trade-off
- Choose four simple tasks, four routine tasks and four complex tasks from recent work.
- Write one acceptance test for each task before asking Copilot.
- Run the same task set once with each tier in a clean branch.
- Record selected model, latency, premium usage, retries and human review minutes.
- Reject any change that fails tests, violates scope or needs material rewriting.
- Compare median cost and time per accepted task for each complexity bucket.
The routing policy should follow the work queue
Efficiency is a sensible default for well-specified mechanical work. Balance is the safest starting point for mixed daily development. Intelligence earns its place when failure or rework is expensive, but only if the acceptance rate actually rises. A team can also classify tickets first and assign the tier by risk instead of giving every prompt the same policy.
Our analysis of Copilot multi-model routing explains why orchestration changes the product even when the model pool stays familiar. The MustHave.ai model selection guide shows how to combine quality, latency and recovery cost in one evaluation.
What administrators should document
- Which tier is the organizational default and who can change it.
- Which task classes require a fixed model for reproducibility.
- How model choice, usage and code-review evidence are retained.
- What cost or failure threshold triggers a routing-policy review.
The practical verdict
GitHub Copilot Auto’s new tiers make the trade-off visible and easier to govern. They do not remove the need for task-level measurement. Start with Balance, test the two edges on real work, and keep fixed-model runs for high-stakes comparisons where a moving route would weaken the evidence.
Primary source
Checked September 14, 2026. Rollout, tier behavior, model-pool scope, billing and the 10 percent paid-subscriber discount come from GitHub. The evaluation matrix and cost-per-accepted-task method are MustHave.ai analysis.