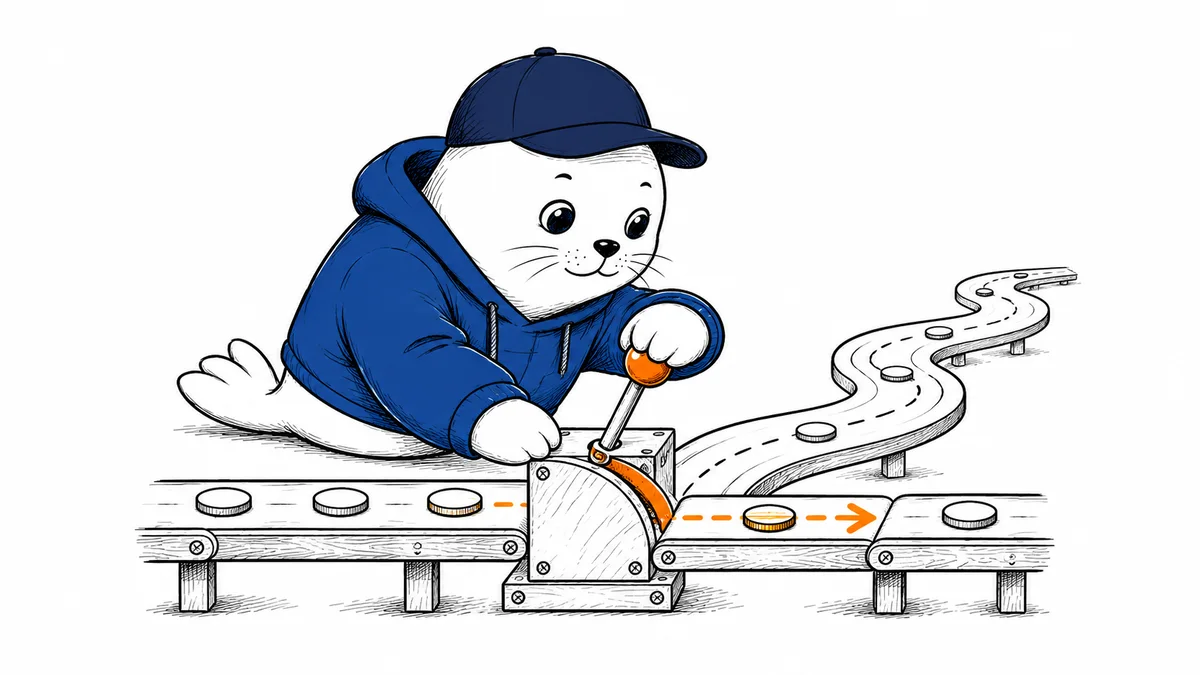
An inference benchmark can jump when the software starts using a fast path that was already available.
Baidu’s November 9 ERNIE Evolve research describes a system that searches for changes to inference code and checks them against fixed constraints. The team reports a 14.9% improvement in decoding throughput on one already optimized setup. A separate low-latency test on Kunlunxin P800 hardware reached 623.6% of its baseline throughput, or 6.236 times that baseline.
Why the baselines matter
The two results come from different tests. Baidu describes cases where the software had an optimized path available but was failing to use it. Fixing when that path runs can produce a large gain if the original code often took a slower route. Hardware, software versions, and request settings can change how much time that decision saves.
Decoding throughput measures the rate at which a model generates output after it processes the input. A service can generate more tokens per second while users still wait for the first token. The research page links to benchmark artifacts. Those artifacts let readers inspect the reported results for the configurations Baidu tested.
Isolate one change before testing throughput
Start with a fixed model, accelerator, input mix, batch size, and output length. Run the baseline repeatedly and record the variation. Apply one optimization, check that output quality still meets your requirements, then record throughput and time to first token separately. If the gain disappears under a longer input or a larger batch, report the conditions under which it holds.
Our ERNIE 5.5 Flash Base coverage looks at access to a separate model release. That distinction matters when planning a test. The Evolve post describes optimization research and benchmark results, so check the linked artifacts for the exact code and data available to reproduce each result.
Abdessalam Alaoui
I'm Abdessalam Alaoui, founder of Musthave.AI. I write practical guides to AI models, tools, generative media.