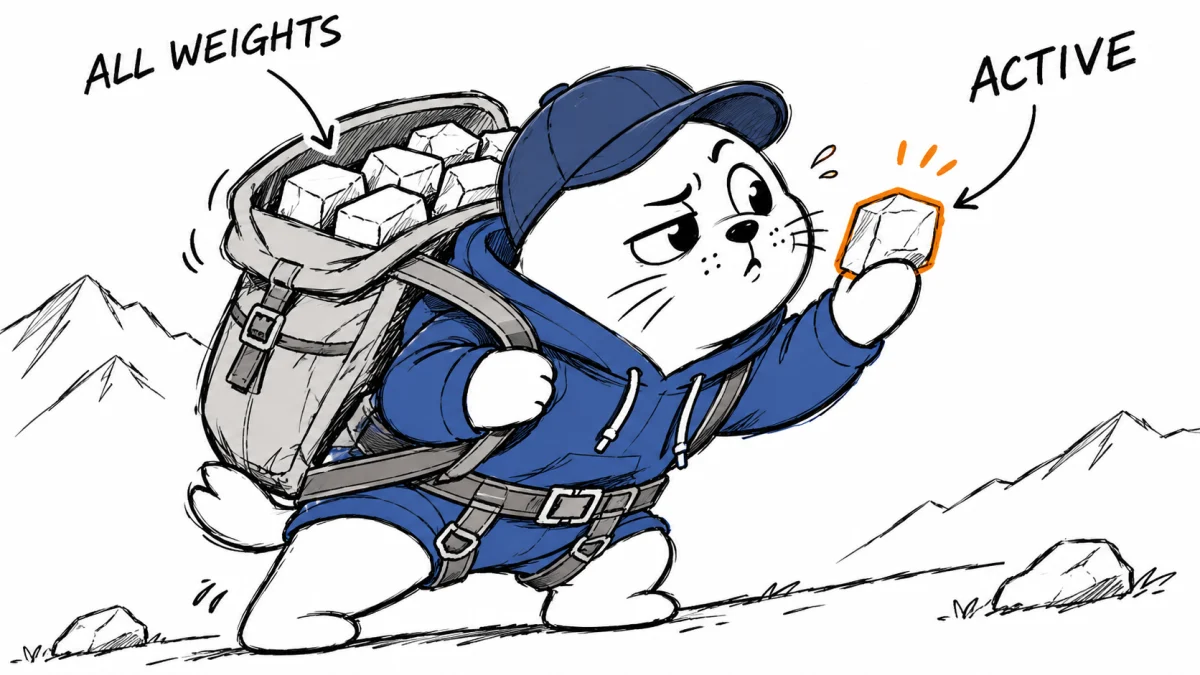
The small active-parameter count reduces computation, but the full checkpoint still needs somewhere to live.
Tencent has published Hy4 Flash, a multimodal mixture-of-experts model with downloadable instruction, FP8, and base variants. Its official model card describes about 220 billion total parameters, including its Engram component, and about 12 billion active parameters per token. It accepts text and images and produces text, with a context window of up to one million tokens.
For a founder considering self-hosting, the two headline numbers answer different questions. Active parameters describe work performed for a token. Total weights describe a much larger collection of learned values that the serving system must make available. The release’s custom license is a separate part of the deployment decision.
Keep Hy4 flash separate from the earlier Hy4 release
Hy4 flash is a specific model and checkpoint family. Its documentation lists an instruction model, an FP8 instruction variant, and a pretrained base model. A base checkpoint and an instruction-tuned checkpoint serve different purposes; choose the exact artifact before judging a result.
Our earlier Hy4 deployment article examined a different release with a 49B-active label and different weight packages. Those file sizes and license details should not be copied onto Flash. A shared product name is insufficient evidence that the deployment requirements stayed the same.
The Flash card also describes architectural components, including sparse and sliding-window attention, routed experts, Engram representations, and a separate drafting component. Those details help explain why a simple dense-model analogy can mislead.
Use the model card and the actual selected files as the deployment record. Keep the repository revision, format, tokenizer, and serving instructions together. An application can behave differently after a model or runtime update even when its prompt stays the same.
What a rough storage calculation can establish
A parameter count can support a simple arithmetic estimate if its assumptions are explicit. Suppose all 220 billion parameter values occupied the same number of bytes. Multiplying the count by that byte width gives the following nominal storage volumes.
| Uniform storage assumption | Calculation | Nominal volume, decimal GB |
|---|---|---|
| Two bytes per parameter | 220 billion × 2 bytes | 440 GB |
| One byte per parameter | 220 billion × 1 byte | 220 GB |
| Half a byte per parameter | 220 billion × 0.5 bytes | 110 GB |
These are illustrative storage calculations. They are not measured checkpoint sizes or a promise that a released format stores every component at the same precision. Format metadata, higher-precision components, alignment, and auxiliary files can change the download size.
Runtime memory needs another calculation. The serving process also needs working buffers and a cache for conversation state, among other allocations. A file that fits on disk may still exceed the usable memory of the intended deployment.
The distinction between decimal GB and binary GiB matters too. The nominal 440 GB example is about 410 GiB. Keep the unit consistent when comparing a file listing with a hardware specification. A unit conversion does not create additional capacity; it changes how the same byte count is expressed.
Active experts do not remove inactive weights
A mixture-of-experts system chooses which expert paths to use for a token. That can reduce the computation needed to process that token. Other tokens may select different paths, so the remaining expert weights are still part of the model.
A deployment can arrange those weights across devices or move some data between memory tiers. Each arrangement changes the engineering problem. Memory capacity, transfer bandwidth, and latency then become part of the performance question.
That is why “12B active” cannot establish the hardware requirements of an ordinary 12B dense model. Start with the full checkpoint and the runtime’s placement strategy. Then measure the workload on the hardware actually under consideration.
A hosted endpoint avoids some self-hosting work, but it raises different questions: which checkpoint the provider serves, what precision it uses, which regions are available, and how usage is billed. A model card’s architecture section does not answer those provider-specific questions.
Read the Tencent Hy License for this release
The Flash repository uses the Tencent Hy License. The text explicitly distinguishes itself from the Apache License 2.0, although it is based on that license with modifications. Calling this release Apache-2.0 would therefore erase relevant terms.
Section 10 defines a model-as-a-service business and describes additional commercial licensing conditions for specified large businesses. Its thresholds include aggregate worldwide gross revenue above US$50 million over a consecutive 12-month period, or use in a product or service with more than 100 million monthly active users in a calendar month.
The definition and exceptions matter as much as the thresholds. The text distinguishes general remote model access from end-user products whose model capabilities remain confined to specific features or workflows. It also addresses internal use and relaying requests to an independently operated third-party service.
A founder comparing deployment options should read those clauses against the actual business arrangement. Selling access to a general model API and using a model inside a narrow product feature can present different facts under the published definition. Keep that distinction in the commercial review rather than relying on the broad phrase “open weights.”
Treat long context as a workload property to verify
The model card advertises up to one million tokens of context. That establishes a documented capacity target; it does not measure speed or answer quality across every input length.
A useful pilot can hold a document question constant while increasing the amount of irrelevant material around its answer. Record whether the model locates the evidence, preserves the right identifiers, and stays within the application’s latency and memory budget. This is a proposed evaluation, not a Hy4 flash result.
For a multimodal workflow, keep text-only and image-containing cases distinguishable. A receipt extractor and a long source-code conversation place different demands on the same model family. A single impressive example cannot establish both use cases.
The published artifacts give developers a real starting point: weights, architectural documentation, and a license they can inspect. A workable adoption decision then connects those artifacts to a named runtime, an actual memory budget, and an acceptable result on the product’s own tasks.

Abdessalam Alaoui
I'm Abdessalam Alaoui, founder of Musthave.AI. I write practical guides to AI models, tools, generative media.