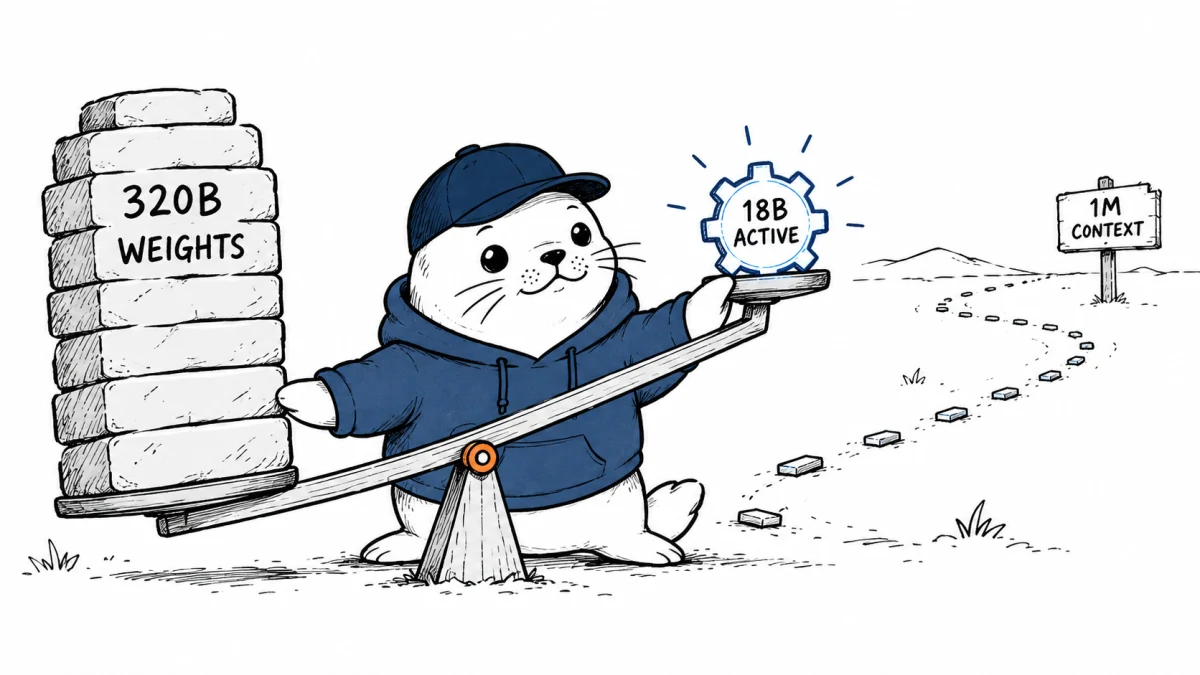
Z.ai released GLM-5.3-Flash on September 16, 2026, as the first natively multimodal model in the GLM-5 family. Its headline numbers sound contradictory: 320 billion total parameters, 18 billion active parameters and context support up to one million tokens. They describe different parts of the deployment problem.
The official GLM-5.3-Flash announcement says the model was trained from a new base on a 30-trillion-token multimodal corpus. The MIT-licensed weights are available on Hugging Face, with deployment guidance for SGLang, vLLM, TokenSpeed, Transformers and KTransformers.
The launch facts at a glance
| Release detail | What Z.ai published | What it means in practice |
|---|---|---|
| Architecture | 320B total, 18B active per token | Mixture-of-experts compute is selective, but the full model still has a very large storage and memory footprint. |
| Inputs | Text, images, video and files | Vision participates in planning and verification rather than acting only as an image-captioning add-on. |
| Context | Up to 1M tokens | Long-context cost depends heavily on attention and KV-cache design. |
| License | MIT | The released weights can be studied, modified and deployed under a permissive license. |
| Serving | Anonymous Ox Alpha traffic ran on Chinese AI accelerators | This is strategically notable, but the hardware and deployment audit remain company-reported. |
18B active does not mean an 18B download
Active parameters describe how much of a sparse model participates in processing a token. Total parameters describe the full collection of expert weights that must be stored and made available to the serving system. GLM-5.3-Flash activates about 5.6% of its 320B parameters for a token, but it does not turn into a small 18B checkpoint.
A simple lower-bound calculation makes the distinction concrete. At two bytes per parameter, 320B parameters would represent roughly 640 GB of raw BF16 weights before runtime overhead, caches and parallelism. FP8 can reduce the raw weight arithmetic substantially, but the system remains a data-center-scale model. These figures are derived estimates, not a measured GLM deployment configuration.
This is the same trap we explained in our Qwen3.8-Flash-Next deployment analysis: active compute can fall much faster than the weight footprint.
Why the attention redesign matters at one million tokens
Z.ai combines linear attention for local dependencies with sparse attention that retrieves selected information from the wider context. Its IndexPool mechanism compresses four cached key vectors into one through weighted pooling. The company reports about three times less attention compute and a 4.4-times smaller KV cache than GLM-5.3 in its comparison.
Those claims address the cost that grows with long conversations, repositories and files. They do not erase the cost of loading and routing a 320B backbone. A buyer should therefore ask two questions separately: how much compute is used for each token, and how much hardware is needed to keep the complete model available?
Native multimodality changes the agent loop
GLM-5.3-Flash was trained jointly on text and visual data. Z.ai positions that capability for documents, spreadsheets, presentations, dashboards and interfaces. The useful shift is not merely that the model can see an image. It can inspect the visual result of an action, judge layout or state, and use that observation to choose the next step.
- A document agent can render a page, find overflow or misalignment and revise it.
- A data agent can compare a chart with the underlying definitions before accepting the output.
- A browser agent can observe interface state and verify whether an operation succeeded.
The benchmark table is useful, but vendor-run
Z.ai reports 84.3 on Terminal-Bench 2.1, 63.4 on DeepSWE v1.1, 78.4 on Toolathlon Verified and 48.8 on AutomationBench v1.0.6. The model card also discloses unusually long generation limits, tool harnesses and context settings for several evaluations.
That detail helps reproducibility, but the numbers remain company-published results. Teams should reproduce the tasks closest to their workload with the same reasoning budget, tool permissions and timeout policy. A ranking without those controls can hide more than it reveals.
Chinese accelerator serving is the strategic claim
Before release, Z.ai tested the model anonymously under the Ox Alpha name and says all traffic was served on Chinese AI accelerators. The company describes tensor parallelism, ReplaySSM, W8A8 quantization, mixed cache quantization and disaggregated encode, prefill and decode stages. It reports a threefold end-to-end improvement over its initial baseline on the same hardware.
This is evidence that the company is designing the model and serving stack together. It is not yet an independent audit of chip utilization, cost or reliability. Our earlier GLM-5.3 analysis explains the broader open-weight and hosted deployment context, while our DeepSeek V4.1 Flash guide shows another Chinese approach to active parameters and KV-cache reduction.
Who should test GLM-5.3-Flash first
The strongest early fit is a team already serving large open-weight models and evaluating multimodal agents over repositories, office files or browser workflows. Small local-model users should not read the 18B-active figure as a laptop requirement. API buyers should wait for an explicit live pricing entry rather than infer a price from older GLM products.
A useful evaluation should record first-token latency, output speed, peak memory, cache growth at several context lengths, visual-tool success and cost per accepted task. That converts an impressive launch sheet into a deployment decision.
Primary sources and disclosure
Checked September 16, 2026. Architecture, serving and benchmark claims attributed to Z.ai are company-reported unless stated otherwise. Raw weight-size estimates are simple parameter-count calculations and not measured production requirements.