September 19 update: GLM 5.3 FlashX reaches Vercel AI Gateway
Update, September 19, 2026: Vercel AI Gateway now lists zai/glm-5.3-flashx, a high-speed serving option for GLM 5.3. Vercel advertises approximately 200 generated tokens per second for faster coding-agent loops and streamed applications. That throughput is provider-reported and will vary with provider route, prompt length, output length and current load.
| Gateway detail | Current listing | Deployment check |
|---|---|---|
| Model ID | zai/glm-5.3-flashx | Pin the exact ID and log it with every result. |
| Serving claim | About 200 output tokens per second | Measure median and tail throughput on the real workload. |
| Maximum output | 131,072 tokens | Set a much lower application cap to bound cost and latency. |
| API formats | AI SDK, Chat Completions, Responses and Messages | Run contract tests because compatible formats can differ at the edges. |
| Routing | Gateway retries, failover and provider sorting | Record which route served the request and whether a fallback changed behavior. |
| Operations | Usage, cost, budgets and request traces | Verify that traces exclude secrets and sensitive prompt content. |
A speed-optimized route changes the serving layer, not the underlying architecture described in the launch analysis. Test time to first token, prompt processing and sustained generation separately. A coding agent can still feel slow at 200 output tokens per second if a long repository context takes seconds to ingest or the workflow makes many sequential tool calls.
- Freeze a representative coding and tool-use prompt set.
- Run the standard Flash and FlashX routes with the same limits.
- Record provider route, cache status, time to first token and output throughput.
- Trigger a controlled failure and confirm retry or fallback behavior.
- Compare task success, not only tokens per second.
- Set an API-key budget and verify the alert before production.
Read Vercel’s GLM 5.3 FlashX availability note and the live model listing. Pricing and provider availability can change, so check the listing at deployment time.
September 17 update: Z.ai details the infrastructure behind GLM-5.3-Flash
Update, September 17, 2026: Z.ai has published an engineering account of the inference infrastructure used for GLM-5.3-Flash. The company says its platform spans more than 100,000 Chinese accelerators and that an internal Infra Agent helped productionize the model in under two weeks while improving throughput by roughly three times.
| Claim or artifact | What it supports | Evidence boundary |
|---|---|---|
| More than 100,000 Chinese accelerators | Scale of Z.ai’s heterogeneous inference fleet | Company-reported, not independently audited |
| Under two weeks to productionize | Reported speed of the Infra Agent workflow | Company-reported and dependent on internal baselines |
| About 3x throughput | Reported optimization gain | Needs workload, hardware and baseline details for comparison |
| 62 trillion tokens in six days | Reported demand during anonymous preview on OpenCode and OpenRouter | Company-reported usage, not model-quality evidence |
| Public model card and vLLM recipe | Reproducible configuration starting points | Inspectable artifacts, but not a reproduction of the fleet claims |
Throughput claims need a denominator
A threefold throughput improvement is meaningful only when the baseline, batch pattern, prompt and output lengths, precision, accelerator type, latency target and software version are known. Teams should not transfer the multiplier directly to their own deployment. The stronger practical evidence is the availability of a model card and a vLLM recipe that can be tested on a named configuration.
A reproducible GLM-5.3-Flash check
- Pin the model revision, vLLM version and recipe.
- Record accelerator model, count, memory and precision.
- Measure prompt and output tokens separately.
- Report throughput beside median and tail latency.
- Repeat with the same workload before and after each optimization.
- Keep company fleet claims separate from the locally reproduced result.
Read Z.ai’s infrastructure engineering account, the GLM-5.3-Flash model card and the vLLM deployment recipe. The original model architecture, context and benchmark analysis continues below.
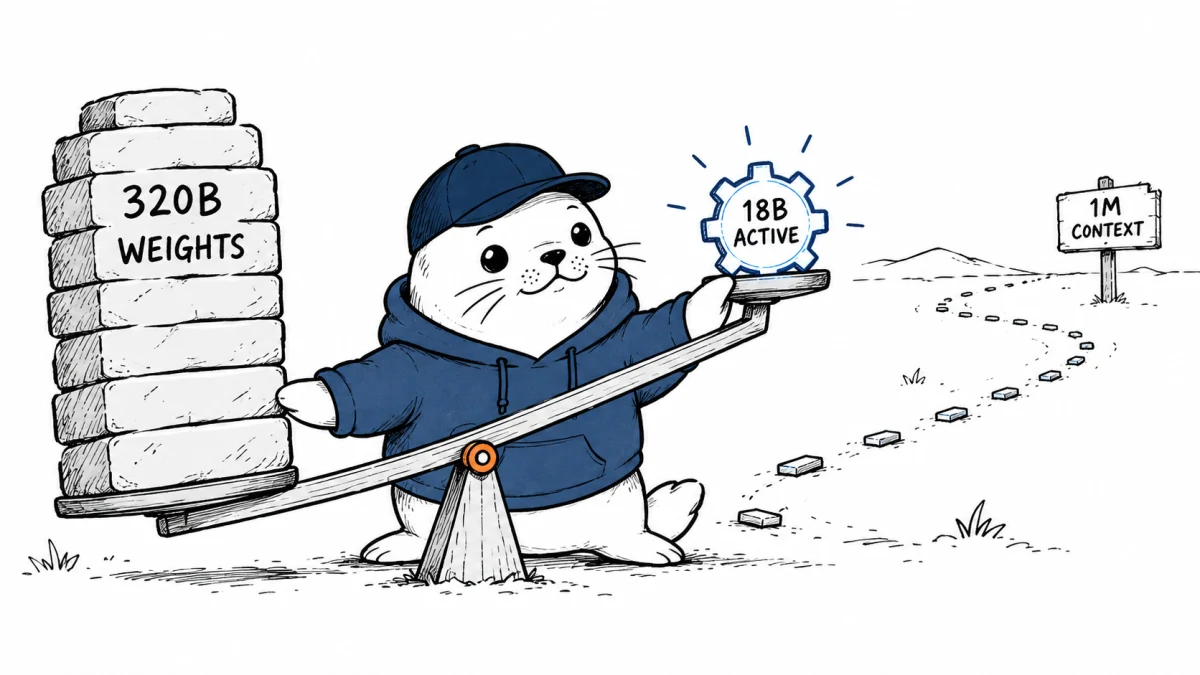
Z.ai released GLM-5.3-Flash on September 16, 2026, as the first natively multimodal model in the GLM-5 family. Its headline numbers sound contradictory: 320 billion total parameters, 18 billion active parameters and context support up to one million tokens. They describe different parts of the deployment problem.
The official GLM-5.3-Flash announcement says the model was trained from a new base on a 30-trillion-token multimodal corpus. The MIT-licensed weights are available on Hugging Face, with deployment guidance for SGLang, vLLM, TokenSpeed, Transformers and KTransformers.
The launch facts at a glance
| Release detail | What Z.ai published | What it means in practice |
|---|---|---|
| Architecture | 320B total, 18B active per token | Mixture-of-experts compute is selective, but the full model still has a very large storage and memory footprint. |
| Inputs | Text, images, video and files | Vision participates in planning and verification rather than acting only as an image-captioning add-on. |
| Context | Up to 1M tokens | Long-context cost depends heavily on attention and KV-cache design. |
| License | MIT | The released weights can be studied, modified and deployed under a permissive license. |
| Serving | Anonymous Ox Alpha traffic ran on Chinese AI accelerators | This is strategically notable, but the hardware and deployment audit remain company-reported. |
18B active does not mean an 18B download
Active parameters describe how much of a sparse model participates in processing a token. Total parameters describe the full collection of expert weights that must be stored and made available to the serving system. GLM-5.3-Flash activates about 5.6% of its 320B parameters for a token, but it does not turn into a small 18B checkpoint.
A simple lower-bound calculation makes the distinction concrete. At two bytes per parameter, 320B parameters would represent roughly 640 GB of raw BF16 weights before runtime overhead, caches and parallelism. FP8 can reduce the raw weight arithmetic substantially, but the system remains a data-center-scale model. These figures are derived estimates, not a measured GLM deployment configuration.
This is the same trap we explained in our Qwen3.8-Flash-Next deployment analysis: active compute can fall much faster than the weight footprint.
Why the attention redesign matters at one million tokens
Z.ai combines linear attention for local dependencies with sparse attention that retrieves selected information from the wider context. Its IndexPool mechanism compresses four cached key vectors into one through weighted pooling. The company reports about three times less attention compute and a 4.4-times smaller KV cache than GLM-5.3 in its comparison.
Those claims address the cost that grows with long conversations, repositories and files. They do not erase the cost of loading and routing a 320B backbone. A buyer should therefore ask two questions separately: how much compute is used for each token, and how much hardware is needed to keep the complete model available?
Native multimodality changes the agent loop
GLM-5.3-Flash was trained jointly on text and visual data. Z.ai positions that capability for documents, spreadsheets, presentations, dashboards and interfaces. The useful shift is not merely that the model can see an image. It can inspect the visual result of an action, judge layout or state, and use that observation to choose the next step.
- A document agent can render a page, find overflow or misalignment and revise it.
- A data agent can compare a chart with the underlying definitions before accepting the output.
- A browser agent can observe interface state and verify whether an operation succeeded.
The benchmark table is useful, but vendor-run
Z.ai reports 84.3 on Terminal-Bench 2.1, 63.4 on DeepSWE v1.1, 78.4 on Toolathlon Verified and 48.8 on AutomationBench v1.0.6. The model card also discloses unusually long generation limits, tool harnesses and context settings for several evaluations.
That detail helps reproducibility, but the numbers remain company-published results. Teams should reproduce the tasks closest to their workload with the same reasoning budget, tool permissions and timeout policy. A ranking without those controls can hide more than it reveals.
Chinese accelerator serving is the strategic claim
Before release, Z.ai tested the model anonymously under the Ox Alpha name and says all traffic was served on Chinese AI accelerators. The company describes tensor parallelism, ReplaySSM, W8A8 quantization, mixed cache quantization and disaggregated encode, prefill and decode stages. It reports a threefold end-to-end improvement over its initial baseline on the same hardware.
This is evidence that the company is designing the model and serving stack together. It is not yet an independent audit of chip utilization, cost or reliability. Our earlier GLM-5.3 analysis explains the broader open-weight and hosted deployment context, while our DeepSeek V4.1 Flash guide shows another Chinese approach to active parameters and KV-cache reduction.
Who should test GLM-5.3-Flash first
The strongest early fit is a team already serving large open-weight models and evaluating multimodal agents over repositories, office files or browser workflows. Small local-model users should not read the 18B-active figure as a laptop requirement. API buyers should wait for an explicit live pricing entry rather than infer a price from older GLM products.
A useful evaluation should record first-token latency, output speed, peak memory, cache growth at several context lengths, visual-tool success and cost per accepted task. That converts an impressive launch sheet into a deployment decision.
Primary sources and disclosure
Step 5 Preview adds another one-million-token sparse model to the comparison set, but its open weights are promised for October 15 rather than available today.
Checked September 16, 2026. Architecture, serving and benchmark claims attributed to Z.ai are company-reported unless stated otherwise. Raw weight-size estimates are simple parameter-count calculations and not measured production requirements.