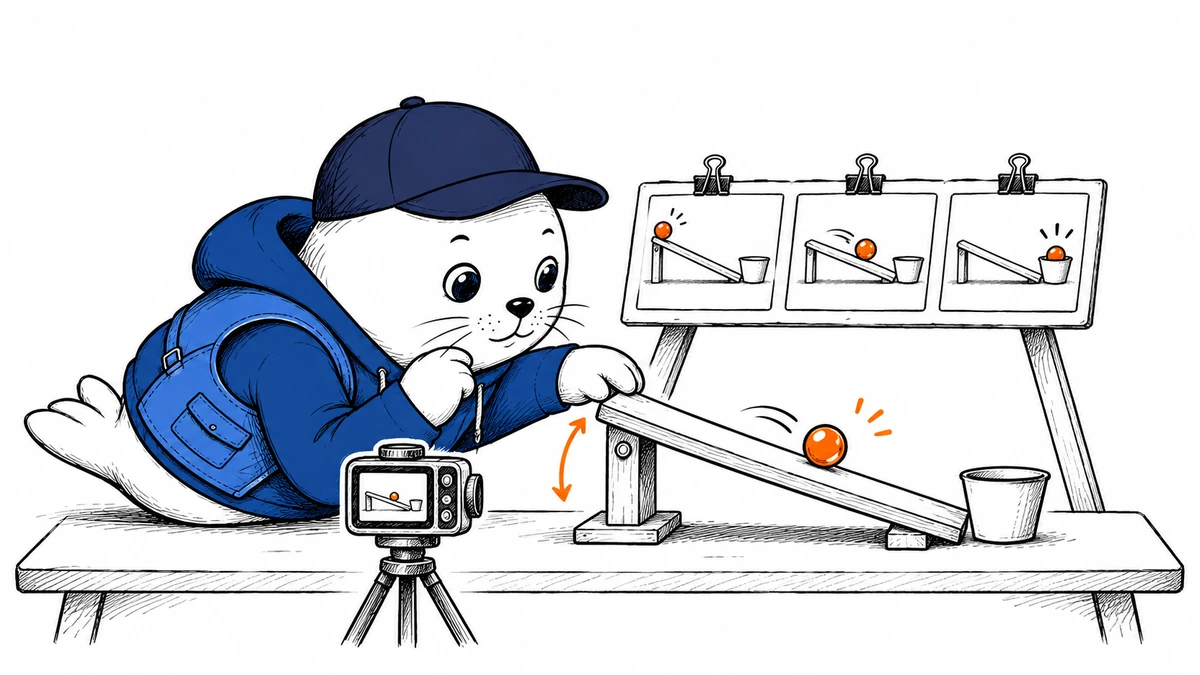
A clip can show a marble in a cup without ever showing it roll down the ramp.
The Institute of Foundation Models at MBZUAI announced PAN 2 on November 10. The world model takes an action described in words and can use an image as a starting point. It generates up to 20 seconds of video. The institute released its own code and 29-billion-parameter diffusion backbone under Apache 2.0. Its model card lists Qwen and Wan components as separate dependencies with their own licenses.
PAN 2 uses a language model to turn the requested action into a structured description, then generates a video conditioned on that description. The authors report that about two in three simulated plans in their study missed at least one step. Their study used plans designed to succeed, so the paper leaves open how well the model depicts plans that should fail.
Score the motion between the first and last frames
Start from a reference image of a marble, ramp, and cup. Ask for three observable events. The marble starts at the top, rolls down the ramp, and comes to rest in the cup. Generate three clips with different seeds. Score each event in order, and record whether the marble stays visible and retains its appearance. A jump from the first state to the final state would miss the middle event, even if the final frame looks right.
That trial would give a builder a more specific picture of whether the clip is useful for planning an action or illustrating it. It is a proposed check, with the institute’s published limitations as its starting point.
Abdessalam Alaoui
I'm Abdessalam Alaoui, founder of Musthave.AI. I write practical guides to AI models, tools, generative media.