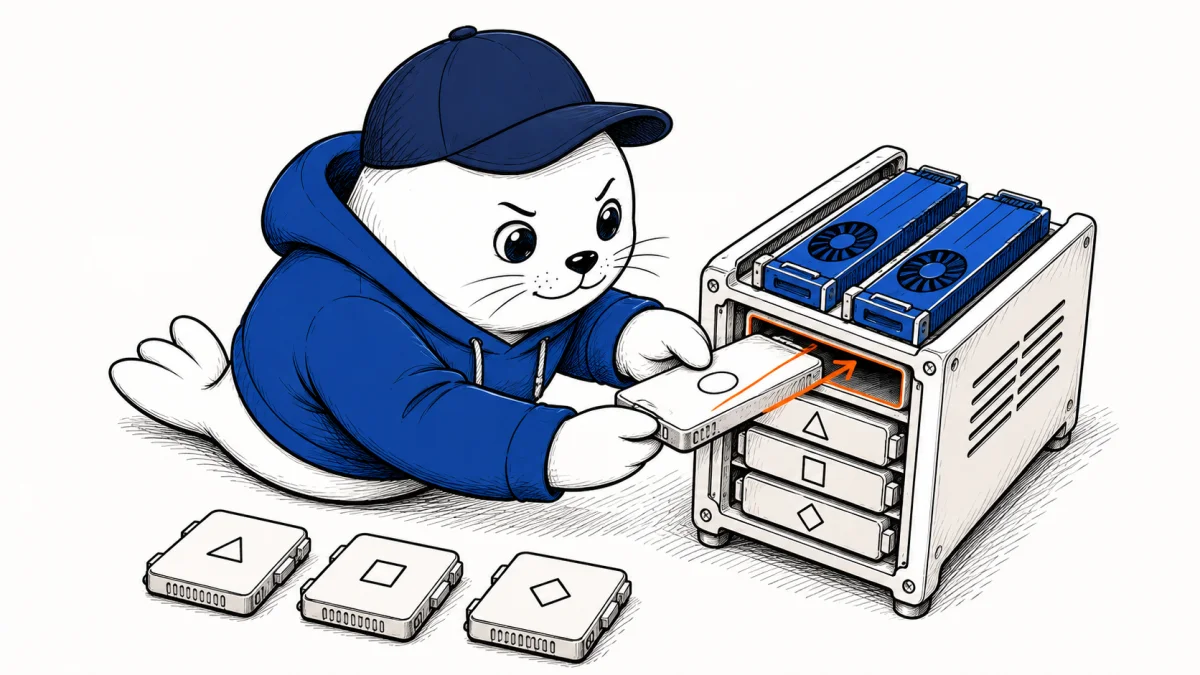
Two recipes can serve the same model and need very different hardware.
NVIDIA’s November 8 Dynamo announcement highlights deployment recipes for four Korean model families: SK Telecom’s A.X K2, LG AI Research’s K-EXAONE 2.0, Upstage’s Solar Open 2, and Motif Technologies’ Motif-3. Dynamo coordinates inference across GPUs. Several configurations appeared in earlier Dynamo release notes, so November 8 is the date of the announcement, not the first release date for every recipe.
Read the deployment configuration before the speed claim
NVIDIA says the B200 recipes can improve performance by up to twofold. The announcement doesn’t provide a single comparable workload for all four models. The recipe inventory is a better starting point: it shows which checkpoint, runtime, and accelerator configuration each setup expects.
| Configuration example | Documented GPU count |
|---|---|
| Motif-3 NVFP4, combined serving | 2 B200 GPUs |
| Motif-3 NVFP4, separate prompt and output workers | 8 B200 GPUs |
| Solar Open 2 250B NVFP4, separate workers | 8 B200 GPUs |
Test against traffic you expect to serve
Separate the time to the first token from the speed of the rest of the response. Long prompts can make the first measure more important; sustained generation can put more pressure on the second. Use the same prompts, output limits, and concurrency on both configurations. Record total GPU use so you can compare capacity as well as speed.
Before reserving hardware, check the recipe catalog for checkpoint access, dependencies, and networking requirements. A recipe with separate prompt and output workers can provide more capacity, but it also adds inter-worker communication. We have not measured the four models on the same hardware.
Abdessalam Alaoui
I'm Abdessalam Alaoui, founder of Musthave.AI. I write practical guides to AI models, tools, generative media.