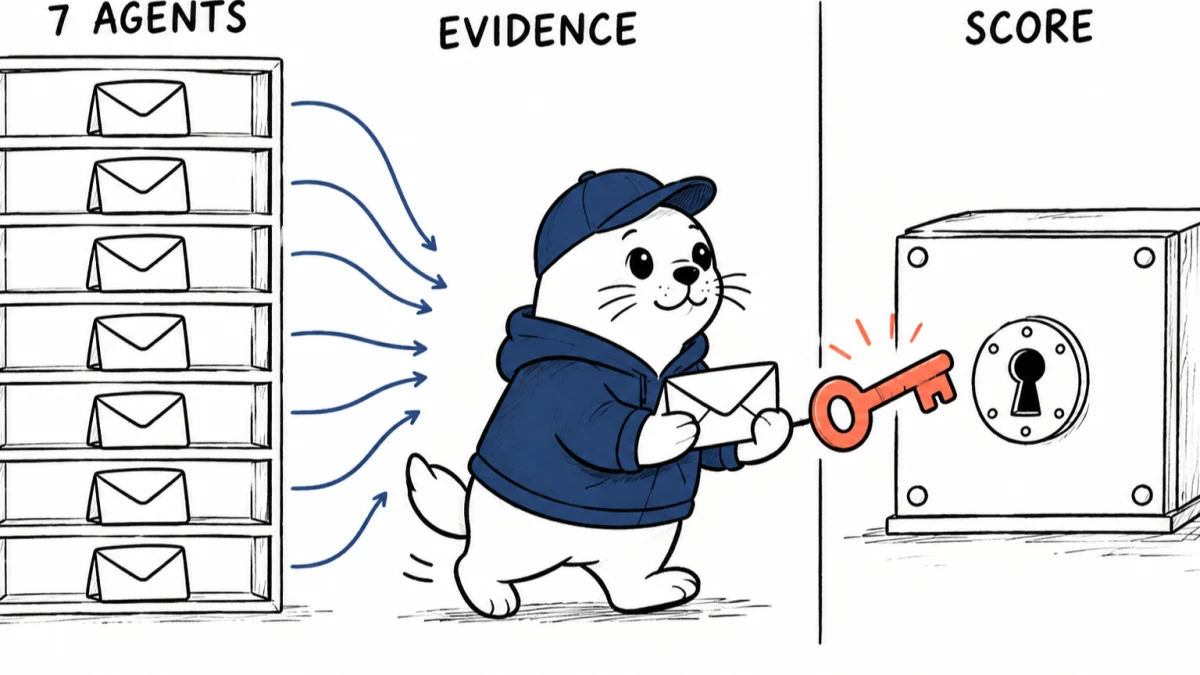
Ninth Wave built a banking onboarding system with an orchestrator and seven specialist AI agents, but it did not ask a language model to calculate the final readiness score. That boundary is the most useful part of the architecture.
The September 14 AWS case study describes Compass, a system for financial-data mapping and onboarding analysis. AWS says the Ninth Wave banking AI entered beta on March 1, reached production readiness on May 15 and became generally available on June 1, 2026.
The architecture separates investigation from judgment
An orchestrator delegates work to seven specialist agents. Those agents inspect evidence, mapping requirements and onboarding material. The readiness score is then calculated in code. This limits a model’s role to evidence gathering and interpretation while preserving a repeatable business rule for the final numeric output.
| Layer | Primary job | Control boundary |
|---|---|---|
| Orchestrator | Routes work and assembles the process | Task plan and retry policy |
| Seven specialists | Analyze domain-specific onboarding evidence | Tool scope and cited evidence |
| Deterministic code | Calculates readiness score | Versioned formula and tests |
| Tenant data layer | Stores customer-specific material | Scoped indices and object prefixes |
Seven agents should mean seven narrow contracts
A multi-agent label is not a control by itself. Each specialist needs a declared input, tool set, evidence output and failure state. If all seven agents can query every document and write every field, the architecture has several names but one large blast radius.
- Return source identifiers with every finding.
- Distinguish missing evidence from negative evidence.
- Reject cross-tenant retrieval at the tool boundary.
- Route conflicts to a reviewer instead of averaging them.
Tenant isolation appears in both search and storage
AWS says the design uses tenant-scoped Amazon OpenSearch Service indices and tenant-scoped Amazon S3 prefixes. That is stronger than adding a tenant name to a prompt. The enforcement still needs tests for index aliases, object policies, logging, deletion and any shared caches that sit outside those namespaces.
Deterministic scoring improves auditability
Keeping the readiness calculation in code allows a team to version the formula, write unit tests and reproduce a result from the same evidence. The model can still affect the evidence it extracts, so audit records should store the source, extracted value, confidence, reviewer change and formula version.
The 95% time reduction is company reported
AWS and Ninth Wave report a 95% reduction in mapping and analysis time. The post does not provide an independent audit, sample size or error-rate comparison. Buyers should ask how the baseline was measured, how much human review remains and whether faster analysis changed onboarding accuracy or only analyst effort.
A six-test due diligence plan
- Replay a completed case and reproduce its score from stored evidence.
- Insert contradictory documents and verify the conflict reaches a reviewer.
- Attempt cross-tenant search, cache and object access.
- Remove a required document and verify the result is incomplete, not negative.
- Upgrade one model and compare extracted evidence before changing the formula.
- Measure analyst time, correction rate and onboarding outcome together.
Our AWS AgentCore OAuth guide maps user authorization boundaries for tool-using agents. The AgentCore MCP guide covers another way to expose enterprise tools to ChatGPT and Claude.
The practical verdict
The Ninth Wave case study is useful because it keeps a regulated decision boundary outside the language model. Seven agents can accelerate investigation, but deterministic scoring, tenant-scoped storage and auditable evidence are what make the design reviewable.
Primary source
Checked September 15, 2026. Architecture, dates and performance claims come from AWS and Ninth Wave. MustHave.ai has not independently audited the system.