“Ranked first” sounds simple. The CDC FluSight result compares probabilistic hospitalization forecasts under a defined scoring method, not a diagnosis score for individual patients.
Google Research announced that its ERA model ranked first in the 2025–2026 CDC FluSight evaluation. The CDC’s evaluation report describes how it scored eligible models against a baseline across forecast targets, weeks, and locations.
What the models were forecasting
The task was to predict weekly influenza hospital admissions using probability distributions. A useful forecast must do more than select one number. It must assign sensible uncertainty to a range of possible outcomes. That is why the evaluation uses a probabilistic score.
This is a population-level public-health forecast. It does not predict whether one person has influenza, whether a particular patient should receive treatment, or how an individual case will progress. Clinical decisions require separate evidence and medical judgment.
How eligibility shaped the field. To enter the main comparison,
CDC required a model to submit forecasts for at least 75% of eligible locations and weeks. This prevents a system from looking strong by forecasting only a small or easy subset. The report says the described scoring excludes the national level and Puerto Rico.
Coverage rules matter when reading any leaderboard. A model that performs well in a limited sample may not be comparable with one that submitted consistently across the evaluation. The eligibility threshold is therefore part of the result, not a footnote.
Relative WIS rewards accuracy and calibration
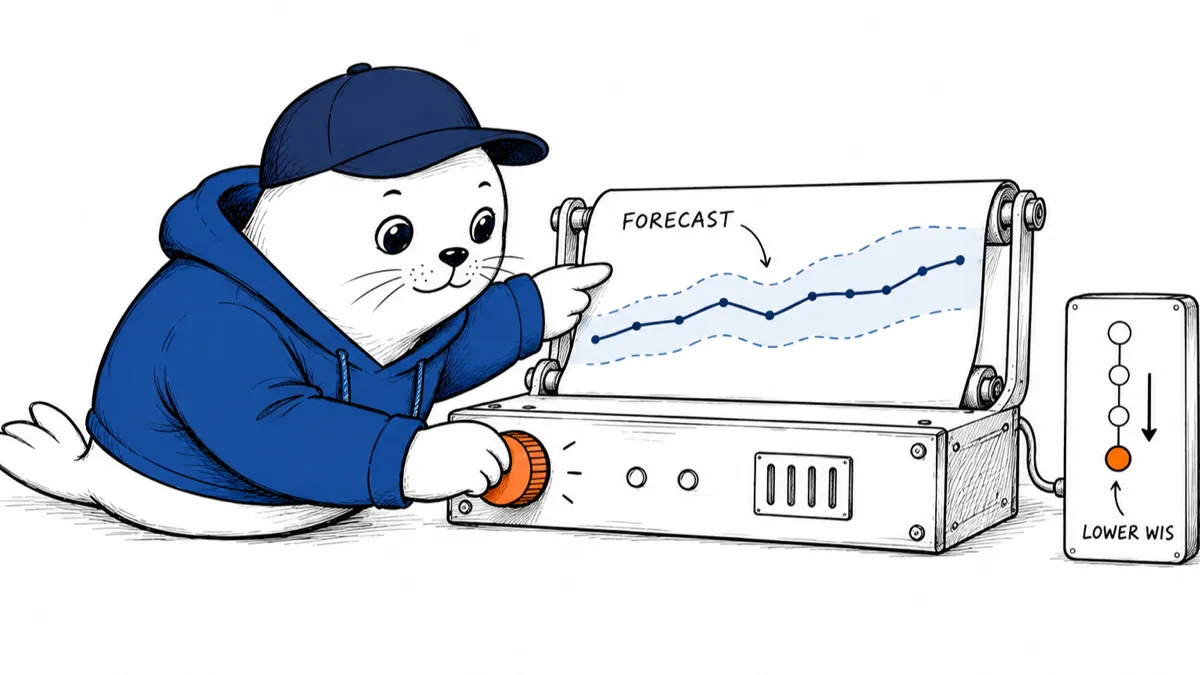
CDC used weighted interval score, then compared each model with a baseline through a pairwise relative measure. Lower relative WIS is better. The score penalizes forecasts that are far from the observed result and uncertainty intervals that are poorly calibrated or unnecessarily wide.
The report also examines coverage for 50% and 95% prediction intervals. If an interval is calibrated, the observed value should fall inside it at roughly the stated frequency over many forecasts. One correct week does not establish calibration; the pattern across the season matters.
What Google’s first-place claim means
Google says ERA ranked first among 39 eligible models. That supports a claim about this evaluation, this season and these scoring rules. It does not prove that ERA will lead every future season, region, or disease. Forecasting conditions change as surveillance data, behavior, and circulating strains change.
It also does not show that the system should replace an ensemble or public-health decision process. A forecaster may be useful because it adds a different signal to a collection, even when it is not ranked first. Operational decisions can depend on stability, update timing, interpretability, and data availability, not just one aggregate score.
Questions for the next season
- Does performance remain strong across regions and forecast horizons?
- How early are forecasts available after new surveillance data arrives?
- How does the model behave during abrupt turning points?
- Does adding ERA improve an ensemble compared with using it alone?
- Are revisions and missing data handled consistently?
Our WeatherNext 3 analysis makes the same broader point: a model headline becomes useful only when the target, resolution, and evaluation boundary are clear. Google’s FluSight result is meaningful evidence about probabilistic hospitalization forecasting. It should stay inside that boundary.