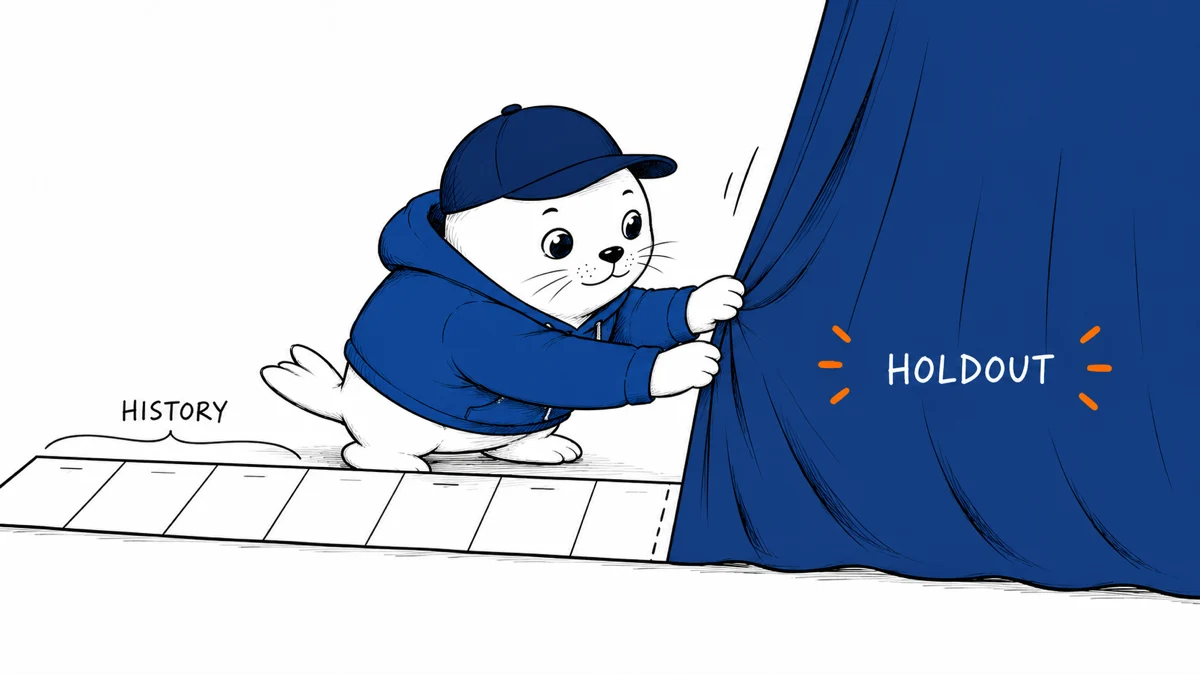
A forecast is useful only if it predicts data that was genuinely unavailable at the time of the decision. A small model still needs that test.
A forecasting family with published inference code
Mistral’s October 15 release introduces four Timestral sizes, from 5 million to 209 million parameters. They jointly forecast related time series and produce 21 quantiles to characterize uncertainty.
The inference repository supports CPU and GPU execution. It accepts past-only variables and variables known over the forecast horizon, with a context limit of 32,768 time steps. A time step follows the sampling interval in your data; it is not automatically a day.
Keep code and weight terms separate
The repository’s code uses Apache 2.0. The model weights are released separately under a Modified MIT license. Read the weight license as well as the repository license before adopting a checkpoint.
Mistral reports benchmark and CPU-latency results. Those are vendor evaluations under particular conditions. We have not reproduced them, and the announcement says a full technical report will follow.
Build a holdout around the real decision
For a daily order forecast, choose a cutoff date and hide everything after it from the input pipeline. Compare Timestral with a simple seasonal baseline, such as the corresponding weekday from the previous week. Repeat the test across several cutoffs.
A planned promotion can be a known-future variable if its schedule was already available at the cutoff. Actual future sales cannot. A revised weather observation also differs from the forecast in place when the decision was made.
- Save the data as it was available at each cutoff.
- Keep the same horizon and sampling interval for every model.
- Score each series and horizon, including quiet periods and demand spikes.
- Record missing-value handling and any preprocessing learned from data.
- Compare forecast error, uncertainty coverage, and total runtime.
Evaluate uncertainty as well as a central prediction
A narrow interval looks confident. It is useful only if observations fall inside it at roughly the intended rate over a suitable evaluation set. Check that rate alongside the cost of overstocking or missing demand.
I would first run the forecast alongside the existing planning process. Record where it changes a decision and whether the evidence supports that change. This is a proposed evaluation, not a claim that Timestral has improved a production forecast here.
Our Muse Spark Open guide explains another model-footprint decision. The DeepSeek version guide covers revisions and provider-specific limits.
Read the sources and plan your next step
- Mistral announcement and model specifications
- Inference code, input handling, and license separation
- Timestral weight license
Which baseline must a new forecast beat before it changes your planning?
Checked October 19, 2026. This is source-based reporting and analysis; proposed checks are not hands-on test results.