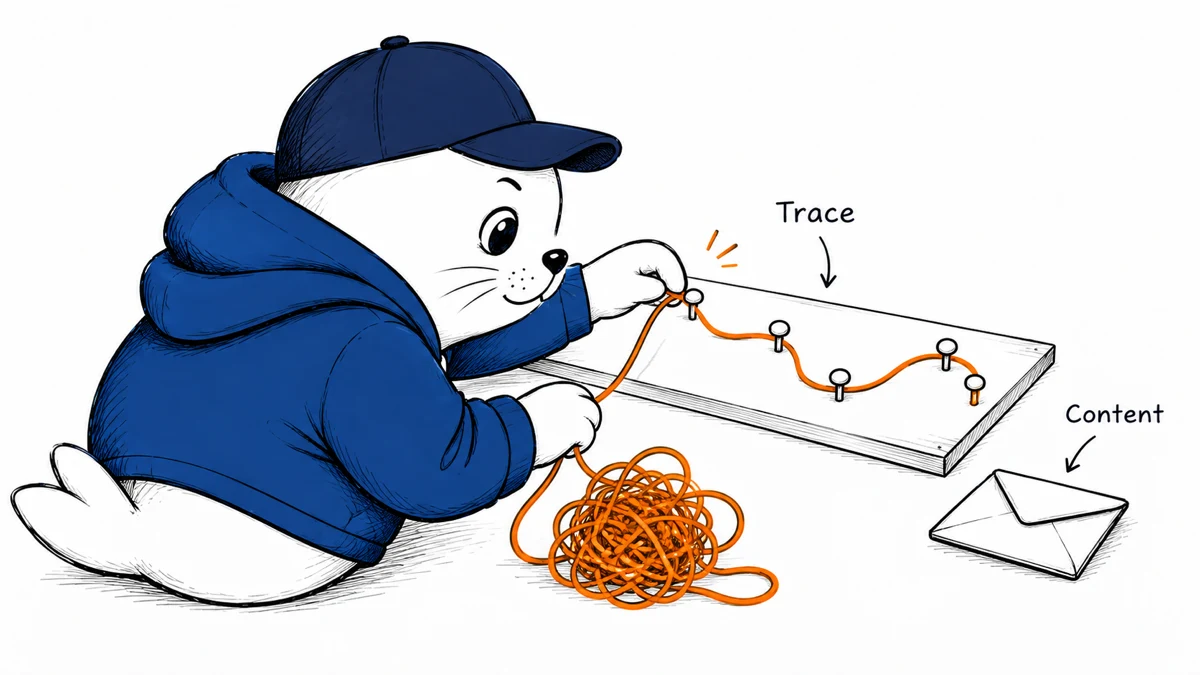
A slow agent run is easier to investigate when you can follow its steps. Decide what those steps should reveal before exporting conversations.
SDK and API tracing answer different questions
Anthropic’s October 14 release notes announce OpenTelemetry export in beta. The documentation separates SDK tracing in application code from API tracing configured through the Console.
API spans expose server-side model runs and tools. SDK spans cover client-side activity, including the tool runner. Combining the two can connect more of a request’s path; API destination setup needs admin permission.
Inspect the metadata-only default
Metadata-only includes identifiers, timing, status, and token counts. It can also include chosen names and descriptions for agents and tools. Full-content mode adds prompts and responses. Your observability provider applies its own storage, access, and retention settings.
Metadata-only should therefore still receive a review. A tool name or description can contain project details even when the conversation itself is absent.
Follow one synthetic request through the export
For a proposed first trial, use a harmless prompt with a unique test marker. Trigger one known client tool and inspect the resulting trace at the destination.
- Check that the expected request and tool steps appear.
- Confirm whether the marker appears in exported fields.
- Verify access using a second account with limited permissions.
- Record destination retention settings.
- Check how retries affect usage totals.
Token usage can appear on multiple related spans. The documentation points to its counting guidance to avoid duplication. For a dashboard, choose one accounting basis and verify its total against a small known request before aggregating traffic.
Enable more content only for a defined question
I would start by asking which failure cannot be diagnosed from timing and status. If conversation content is necessary, define who can read it and how long it remains available before changing the mode.
The export is still a beta. A trace helps explain execution; it does not prove the final answer or tool action was correct. Keep outcome checks beside the telemetry.
The Copilot telemetry guide covers GitHub’s separate controls. Our agent memory guide offers a bounded trial for checking remembered context and permissions.
Read the sources and plan your next step
Which failure would you investigate first with traces: latency, repeated tool calls, or missing context?
Checked October 15, 2026. This is source-based reporting and analysis;the proposed checks are not hands-on test results.