OpenAI launched GPT-6 Sol and GPT-6 Luna on September 22, 2026, cutting API prices in half versus the corresponding GPT-5.6 models and extending Astra-era improvements to cheaper tiers.
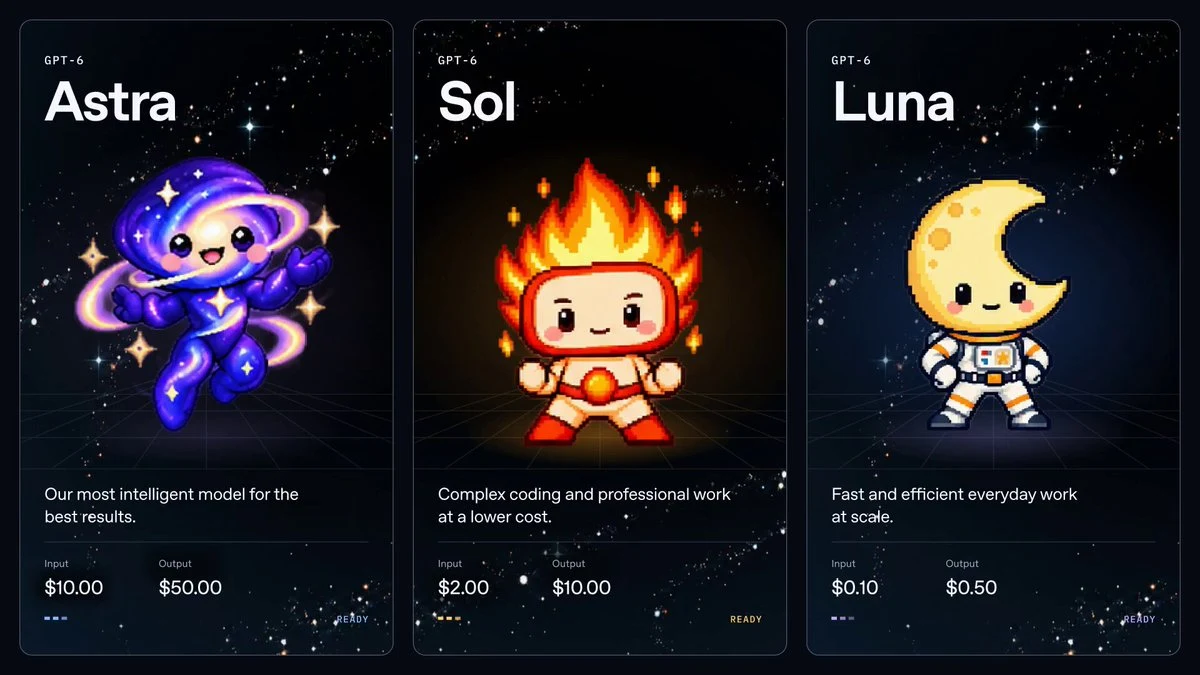
The GPT-6 Sol Luna release is not a simple model rename. It changes the price-performance choices available to developers, especially for coding agents, business workflows and repeated conversations with large cached prefixes. Sol costs $2 per million input tokens and $10 per million output tokens. Luna costs $0.10 per million input tokens and $0.50 per million output tokens. Those are the standard short-context rates published at launch.
The launch in one table
| Model | Input per 1M tokens | Output per 1M tokens | Best initial fit |
|---|---|---|---|
| GPT-6 Astra | $10 | $50 | Highest-stakes and hardest end-to-end work |
| GPT-6 Sol | $2 | $10 | Complex coding and professional work at lower cost |
| GPT-6 Luna | $0.10 | $0.50 | High-volume everyday work and inexpensive agents |
OpenAI says both new models were trained with methods similar to GPT-6 Astra and inherit improvements in professional work, factuality, coding, computer use and alignment. That does not make them equal to Astra. OpenAI still positions Astra as the uncompromising option, while Sol and Luna move the cost curve for workloads that do not need the largest model on every step.
Sol is the practical coding and workflow tier
Sol is the more consequential launch for teams that currently route most difficult work to a premium model. OpenAI reports a 33.2% score for GPT-6 Sol at xhigh effort on AutomationBench at an estimated $0.27 per task. Its release post compares that with 30.3% for low-effort Astra and 26.9% for Claude Opus 5 at max effort, while warning that benchmark costs depend on the harness and task mix.
On FrontierCode 1.1, OpenAI says Sol matches Claude Fable 5.1 at xhigh effort at a much lower estimated cost. On DeepSWE 1.1, Sol at max effort scored 68.8%, within 1.1 points of the Claude Fable 5 result cited by OpenAI. These are vendor-reported comparisons, not an independent guarantee for a particular repository. The useful decision is to test Sol against the code review, build and repair tasks your team actually ships.
Luna changes the economics of high-volume work
Luna’s $0.10 input and $0.50 output rates make it a candidate for classification, summarization, document extraction, support triage and lightweight subagents. Its low price also changes routing design. A system can let Luna attempt a task first, check the result, and escalate only uncertain or high-risk cases to Sol or Astra.
OpenAI reports that Luna at max effort scored 66.6% on DeepSWE 1.1 and that high-effort Luna improved 5.4 percentage points over GPT-5.6 Luna on AutomationBench at 58% lower estimated cost per task. That is a strong launch claim, but the model’s advantage will depend on output length, retries, tool calls and validation. A cheap token price can still produce an expensive workflow if the model loops or hands work back to a larger model.
Caching is part of the product, not a footnote
OpenAI also changed how developers can manage repeated context. GPT-6 offers a 90% discount on cached input-token reads, a dashboard for monitoring cache behavior, diagnostics for missed cache opportunities, and explicit breakpoints for choosing where a cached prefix ends. Changing reasoning effort or enabling and disabling tools no longer has to invalidate earlier cached context.
This matters for coding agents that repeatedly ingest repository instructions, schemas and tool definitions. It also matters for long customer or research conversations. Our earlier analysis of the GPT-6 Astra long-context price multiplier explains why teams should model the full request shape instead of comparing only the headline rate.
Availability is broad, but the product surfaces differ
GPT-6 Sol and Luna are rolling out in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise and Edu users. Free and Go users can try Luna in the desktop app. OpenAI says the models are not yet available in the standard Chat experience. In the API, the model IDs are gpt-6-sol and gpt-6-luna.
That distinction prevents a common launch-day mistake: seeing a model in Codex or ChatGPT Work does not mean it is selectable in every ChatGPT surface. Rollout is gradual, so accounts may receive access at different times. Teams should also confirm current rate limits and regional processing options before changing production routing.
A migration plan for builders
- Export a representative set of successful and failed production tasks.
- Run Astra, Sol and Luna with the same tools, timeouts and evaluation rubric.
- Measure total tokens, tool calls, retries, wall time and reviewer corrections.
- Test cache hit rates using real repeated prefixes, not synthetic one-shot prompts.
- Route by risk: Luna for reversible volume, Sol for complex work and Astra for the hardest or highest-stakes cases.
Users comparing coding products should also separate the model from the harness. Our Codex versus Claude Code guide explains how permissions, context management, review gates and tool design can change the result even when the underlying model is strong.
What the benchmarks do not settle
OpenAI’s release includes meaningful benchmark detail, but most comparisons are reported by OpenAI and depend on effort settings, harnesses and task-cost estimates. A top score does not establish reliability on a private codebase, a regulated document workflow or an organization’s exact tool permissions. The safest conclusion is narrower: GPT-6 Sol and Luna materially lower the published price of the GPT-6 family while preserving access to advanced reasoning controls.
Primary sources
- OpenAI: Introducing GPT-6 Sol and Luna
- OpenAI Deployment Safety Hub: GPT-6 Astra card with Sol and Luna appendix
- OpenAI’s official launch post on X
Checked September 22, 2026. Prices are per one million tokens and can vary for long context, regional processing, batch or fast modes.