A home robot that works in one staged kitchen is a demonstration. A robot that enters unfamiliar homes and completes the same job is a generalization test. Figure has published a larger version of that test, with a result worth reading carefully.
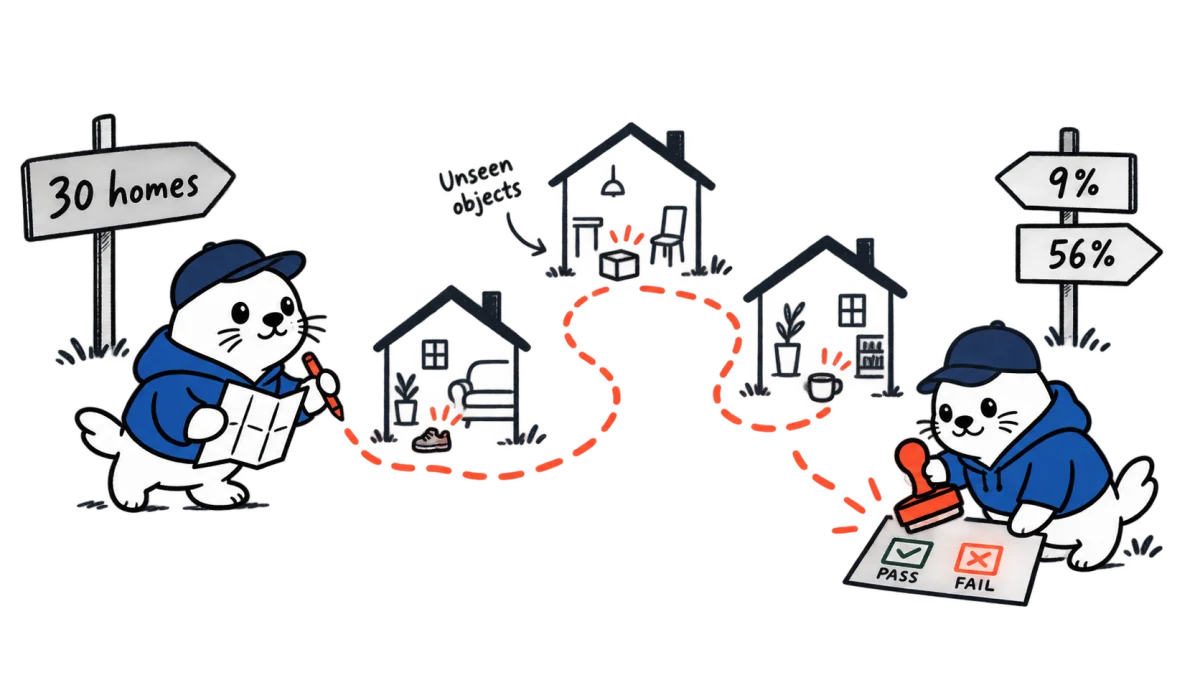
Figure Helix 2.5 achieved a company-reported 56% success rate on three tasks across 30 unseen Bay Area homes, compared with 9% for the baseline. Figure attributes the jump to its Index pretraining method. The company used one fixed checkpoint per task and says it awarded only full-task success, not partial credit.
The benchmark in one table
| Question | Figure’s protocol | Why it matters |
|---|---|---|
| Where? | Thirty previously unseen homes. | Tests visual and physical variation beyond a single lab. |
| What? | Three household tasks. | Broad enough for variation, not broad enough to represent all home work. |
| Which model? | One fixed checkpoint per task. | Avoids selecting a new checkpoint for each home. |
| How scored? | Full success or failure, no partial credit. | Makes the headline rate stricter and easier to interpret. |
| Result? | 9% baseline and 56% with Index. | Large company-reported gain awaiting outside replication. |
What zero-shot means here
The homes and household objects were unseen in the evaluation setup. The tasks were not invented at evaluation time: Figure says the policies were fine-tuned for those tasks in other environments. Zero-shot therefore describes transfer to new layouts and objects, not a robot learning any new instruction without task-specific training.
That is still useful. Homes vary in lighting, geometry, clutter, container design and object placement. A policy that survives those shifts is more valuable than one fitted to a fixed room. But readers should not turn this result into a claim of general household autonomy.
The denominator deserves attention
A 56% success rate means failure remained common under the tested conditions. Product readiness depends on what happens during those failures: whether the robot stops safely, damages an object, blocks a person or requests help. The public headline gives task completion, not a complete safety taxonomy.
A buyer would need the number of trials per home, confidence intervals, failure categories and performance by task. Aggregate success can conceal one easy task and one weak task. It can also conceal repeated failures in a specific layout or object class.
Why the 9% baseline is important
The baseline makes the 56% result more meaningful than an isolated score, because both systems face the same evaluation frame. Yet the value of the comparison depends on what changed besides Index pretraining. Compute, data mixture, optimization time and model size can all contribute unless held constant and reported.
Figure describes Index as the central cause. Until code, checkpoints or independent evaluations are available, that attribution should remain company-reported rather than established fact.
Home selection can shape the result
Thirty homes provide meaningful variation only if selection avoids a narrow cluster of layouts, objects and accessibility conditions. A stronger report would describe how homes were recruited, whether evaluators could exclude difficult sites and how many trials were abandoned before scoring. Pre-registering those rules would reduce the risk that the evaluation set quietly favors the system.
What a stronger follow-up would publish
- Per-task and per-home results with trial counts and uncertainty.
- A failure taxonomy covering perception, planning, grasping, recovery and safety stops.
- Matched compute and data ablations that isolate the effect of Index.
- Independent homes selected and scored by an outside evaluator.
- Recovery tests after objects move, people interrupt or the environment changes mid-task.
How to evaluate the next humanoid demo
Ask four questions in order: Was the environment unseen? Was the task unseen? Was the checkpoint fixed? Was scoring defined before the run? A polished video can answer none of them. A credible benchmark should answer all four and publish failure footage, not only successes.
For broader context, our guide to NVIDIA Isaac Sim 6.1 and physical AI testing explains the simulation layer. Our report on verifying AI productivity claims applies the same rule: define the comparison and outcome before accepting the percentage.
Verdict: stronger evidence, not general home autonomy
Figure’s 30-home evaluation is more informative than a hand-selected lab demonstration. The fixed checkpoints and full-task scoring are positive signs. The remaining gap is external replication and failure detail. Helix 2.5 shows improved transfer to unfamiliar homes, while 56% also shows how much work remains.
Read the primary record
Checked September 18, 2026. Product details and reported results come from the linked first-party sources. Interpretation, limitations and implementation advice are MustHave.ai analysis.